Every data team eventually faces the same question. A number in a report looks wrong, and someone needs to know where it came from.
Data lineage tools exist to answer that. They scan databases, transformation jobs, and reporting tools, then assemble a map showing how data moves from source system to dashboard, including what each transformation did along the way. Good ones let you start at a single field and walk backwards to its origin, or start at a source table and see everything downstream that breaks if you change it.
The question is getting harder to answer.
Gartner's January 2026 press release on zero-trust data governance predicts that by 2028, half of all organizations will adopt a zero-trust posture for governance, since data can no longer be assumed trustworthy or human-generated.
Platforms differ in how far that trace reaches. Coverage varies by system, granularity by connector, and both gaps stay invisible in a demo.
The comparison below scores nine platforms on lineage depth, integration reach, governance, and deployment effort, drawing on what their users report.
What are data lineage tools?
Data lineage tools are software platforms that automatically discover, map, and visualize how data moves across an organization's systems. They record where data originates, how it is transformed, and where it is consumed, giving teams a current view of dependencies for governance, compliance, impact analysis, and troubleshooting.
Manual documentation is only accurate at the moment it is written. Modern platforms handle data lineage tracking continuously, parsing SQL, ETL scripts, and BI metadata so the map updates as pipelines change instead of during an annual documentation push.
What varies between platforms is scope. Some capture lineage only inside their own warehouse or BI tool. Others parse source code across the full stack, including legacy ETL. The difference stays invisible until data crosses a system boundary, which is where most audit questions start.
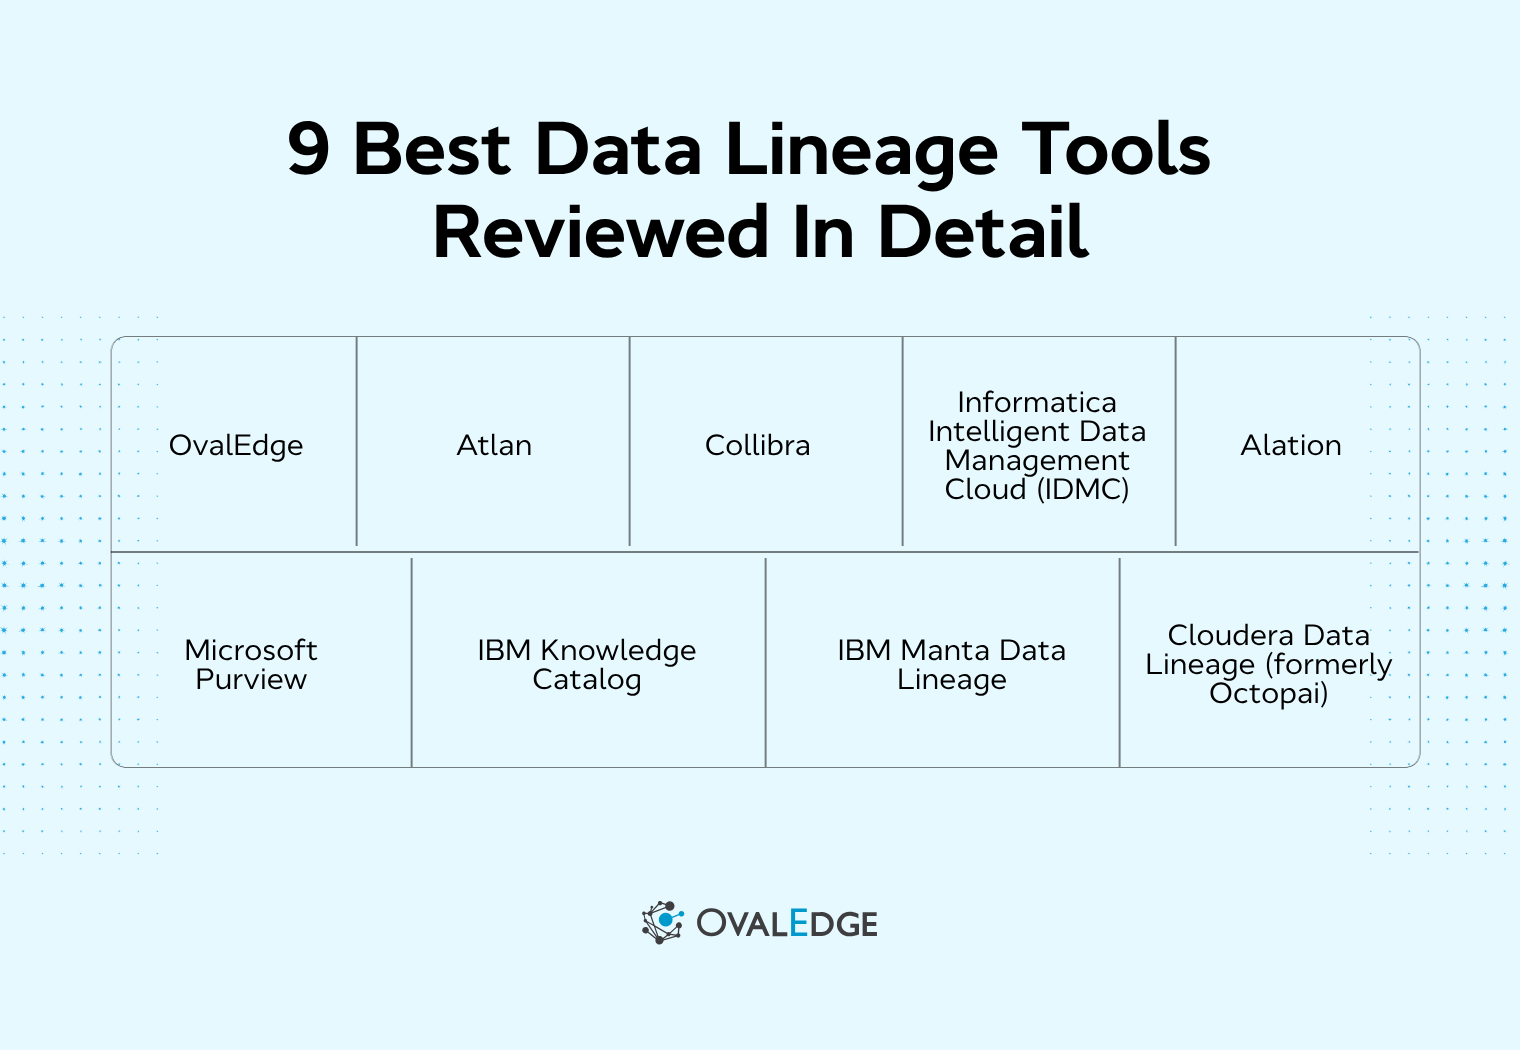
9 best data lineage tools reviewed in detail
The nine platforms below are split into governance suites, parsing engines, and cloud-native catalogs. Read the group that matches your estate first. Each entry covers what the tool does, five core capabilities, what reviewers praise, where it falls short, and who it suits.
1. OvalEdge
OvalEdge is a data governance platform that combines automated column-level lineage with a data catalog, business glossary, data quality monitoring, and access control in a single product. It deploys as SaaS or on-premises, which matters for organizations that cannot move regulated workloads into a vendor cloud.
Key features
-
Automated column-level lineage: Traces individual fields from source to consumption across databases, ETL pipelines, warehouses, and BI tools, without manual mapping.
-
Source Code Intelligence: Reads production code as the source of truth, capturing formulas, joins, and transformations as they exist rather than as documentation claims.
-
Catalog and glossary together: Links technical assets to business definitions and ownership, so analysts can read a lineage graph without an engineer translating it.
-
Impact analysis: Surfaces upstream and downstream dependencies before a schema or logic change ships.
-
Fine-grained access control: Applies column and row-level policy across connected systems, with access requests routed through Jira or ServiceNow.
-
Connector coverage runs to 170+ native integrations spanning modern cloud platforms and legacy systems.
Pros
-
Reviewers single out connector breadth, noting that most systems connect with minimal configuration.
-
Catalog and glossary modules draw repeated praise for being usable by non-technical staff, which is where governance rollouts usually stall.
-
Implementation flexibility rates highly, with reviewers citing configurable modules and a support team that builds missing connectors on request.
Best fit: Mid-market and mid-to-large enterprises that want catalog, lineage, glossary, quality, and access control from one vendor.
See lineage on your own stack.

Lineage claims are hard to judge from a feature list. A demo runs OvalEdge against your systems, so you can see how far the column-level graph actually reaches across your warehouse, ETL, and BI layers before you commit.

Book a demo now.
2. Atlan
Atlan is a cloud-native data catalog built around active metadata, with lineage embedded in the catalog rather than delivered as a separate module. Its connector library focuses on modern cloud platforms including dbt, Snowflake, Databricks, BigQuery, and Looker.
Key features
-
Automated lineage across cloud platforms. Maps data movement between warehouses, transformation tools, and BI layers, refreshing as pipelines change.
-
Active metadata. Continuously enriches assets with usage, ownership, and quality signals, so documentation stays current without manual upkeep.
-
Extensible data model. Lets teams customize asset metadata and extend the model programmatically through the API.
-
Business glossary. Connects business definitions to technical assets, supporting consistent terminology across teams.
-
Governance workflows. Handles certification, ownership, and documentation, with access managed through its Personas and Purposes model.
Pros
-
Search and asset discovery are the strongest parts of the product, with a short path to first value.
-
Lineage gets used for dependency tracing and impact analysis rather than sitting as a diagram.
Cons
-
Lineage views cannot be filtered by asset source, so isolating dbt or Snowflake lineage means reading the full graph.
Best fit: Cloud-first teams on dbt, Snowflake, Databricks, or BigQuery who want lineage inside the catalog and can absorb the onboarding curve.
3. Collibra
Collibra is an enterprise data intelligence platform that combines catalog, governance, lineage, and data quality in a single environment. It includes policy management, stewardship workflows, and privacy handling.
Key features
-
End-to-end lineage: Traces movement and transformation across enterprise systems, scoring 8.1 on G2's data lineage measure.
-
Integrated data catalog: Centralizes technical and business metadata, with automated synchronization from cloud data platforms.
-
Business glossary: Standardizes terms and links them to technical assets, Collibra's highest-rated capability on G2 at 8.4.
-
Governance workflows: Runs policy management, stewardship, approvals, and audit trails, with workflow versioning added in recent releases.
-
Privacy and DSAR handling: Manages data subject access requests, one of the platform's strongest reviewer-rated areas.
Pros
-
Catalog, governance, lineage, quality, and AI governance run in one environment, giving business and IT a shared vocabulary.
-
Connector breadth for metadata ingestion is matched by unusually deep customization.
Cons
-
Lineage capture degrades once an estate mixes several tools, and older systems such as VSAM and ISAM are unsupported.
Best fit: Regulated enterprises with audit obligations, dedicated governance headcount, and budget for a full program rather than a lineage tool alone.
4. Informatica Intelligent Data Management Cloud (IDMC)
Informatica IDMC bundles ETL, data quality, cataloging, and governance into one platform, with its CLAIRE engine handling metadata classification and recommendations. Salesforce completed its acquisition of Informatica in November 2025 for approximately $8 billion.
Key features
-
Code-level lineage. Parses SQL, stored procedures, and ETL logic to build lineage across hybrid and legacy environments rather than cloud platforms alone.
-
CLAIRE metadata automation. Applies AI to classification and metadata recommendations across hybrid and multi-cloud estates.
-
Enterprise metadata management. Collects metadata through a large connector network, with data discovery rated 8.7 by G2 reviewers.
-
Data quality integration. Ties lineage to profiling, cleansing rules, and quality monitoring inside the same platform.
-
Policy enforcement. Scores 8.5 on G2's policy enforcement measure, supporting governance across regulated estates.
Pros
-
Search and discovery surface assets buried across large landscapes, with profiling and quality context attached.
-
Legacy and complex ETL coverage reaches systems most cloud-native catalogs cannot read.
Cons
-
Lineage visualization is hard to read, and automated derivation needs work before root cause analysis becomes straightforward.
Best fit: Large enterprises with heterogeneous legacy and cloud estates, specialist administrators to run the platform, and tolerance for a heavy implementation footprint.
5. Alation
Alation is a data intelligence platform that builds its catalog and lineage from behavioral signals, parsing SQL query logs to infer relationships and rank assets by usage. It covers stewardship, certification, and business glossary alongside discovery.
Key features
-
Query log-based lineage. Parses SQL query history to construct lineage and infer undocumented relationships without manual tagging.
-
Behavioral intelligence. Ranks assets by real usage, so search surfaces what teams rely on rather than what happens to be documented.
-
Business glossary. Links definitions to technical assets, rated 8.4 on G2.
-
Data catalog and discovery. Scores 8.7 for data discovery, with collaboration features for annotating and sharing context.
-
Stewardship and certification. Handles ownership assignment, asset certification, and policy management across governance programs.
Pros
-
Support quality is the standout; reviewers describe the vendor relationship as strong from evaluation through implementation and beyond.
-
Search and the collaboration layer spread data context past the engineering team.
Cons
-
Lineage Analytics has moved on and off the roadmap repeatedly, making it hard to plan around.
Best fit: Enterprises running a catalog-led governance program where adoption and self-service discovery matter more than deep technical lineage across legacy systems.
6. Microsoft Purview
Microsoft Purview is a governance platform covering data discovery, sensitivity classification, and lineage across Azure, Microsoft 365, and Fabric. Lineage coverage and granularity vary by source system, with column-level detail available for a defined set of connectors.
Key features
-
Automated lineage across Azure services: Captures data movement from Data Factory, Synapse, SQL databases, and Power BI into a single map.
-
Sensitive data classification: Scans and labels regulated data automatically, one of the platform's strongest reviewer-rated capabilities.
-
Unified data catalog: Inventories assets across Microsoft and connected non-Microsoft sources with searchable metadata.
-
Manual lineage: Lets teams document lineage for sources automation does not cover, including column mappings, without writing code.
-
Compliance and access controls. Integrates governance policy and data protection across the Microsoft ecosystem.
Pros
-
Native integration across Azure, Microsoft 365, and Fabric removes most early connector work.
-
Classification and scan rule sets handle sensitive data identification at scale.
Cons
-
Column-level lineage for Power BI requires Azure SQL Database as the source, and Fabric items outside Power BI capture item-level lineage only.
Best fit: Azure and Microsoft 365 estates that want governance bundled into existing licensing and can work within table-level lineage outside a short list of supported sources.
7. IBM Knowledge Catalog
IBM Knowledge Catalog is the governance and cataloging component of IBM's data and AI portfolio, now part of watsonx.data intelligence. Lineage is delivered through the separate Manta Data Lineage service, which IBM acquired in 2023.
Key features
-
Manta-powered lineage. Requires the Manta Data Lineage service enabled alongside Knowledge Catalog, which then delivers table and column-level tracing.
-
Enterprise metadata management. Centralizes technical and business metadata across IBM and third-party sources.
-
Business glossary. Standardizes terminology and links it to governed assets.
-
Data quality rules. Applies quality checks and scoring inside the same governance framework.
-
AI-assisted discovery. Classifies and recommends assets to speed up discovery across large catalogs.
Pros
-
Lineage inherits Manta's code parsing, reaching legacy systems that cloud-native catalogs cannot read.
-
Governance, quality, and cataloging sit inside one framework for IBM-committed estates.
Cons
-
Lineage requires a separately licensed Manta service rather than arriving as a native catalog feature.
Best fit: Organizations already standardized on IBM's data and AI portfolio with the administrative capacity to run Cloud Pak services.
8. IBM Manta Data Lineage
Manta is a dedicated lineage tool rather than a governance platform, building maps by parsing code across SQL, stored procedures, ETL workflows, and BI report definitions. It ships standalone and as the lineage layer inside watsonx.data intelligence.
Key features
-
Code-based lineage scanning. Reads SQL, stored procedures, ETL workflows, and BI report definitions to build lineage from what the code does rather than what happened to run.
-
Table and column-level granularity. Resolves lineage down to individual fields across every system it parses.
-
Direct and indirect lineage. Separates elements that carry data from elements that influence it, such as filter and join conditions.
-
Visualization controls. Offers dynamic filtering, color coding by asset category and technology, and tagging to keep large graphs readable.
-
Catalog and CI/CD integration. Exposes lineage through APIs so it feeds metadata catalogs, pipelines, and governance systems rather than living in isolation.
Pros
-
Legacy parsing reaches Informatica PowerCenter, DataStage, SAS, and Cognos at scale.
-
Indirect lineage shows which filter or join conditions influenced a value, not just which columns fed it.
Cons
-
Standalone roadmap cadence has slowed as the product folds into watsonx.data intelligence, so lifecycle commitments are worth confirming.
Best fit: Enterprises carrying material legacy ETL who need forensic lineage depth and already run a catalog.
9. Cloudera Data Lineage (formerly Octopai)
Cloudera acquired Octopai in November 2024 and now ships the product as Cloudera Data Lineage. It covers lineage, discovery, and cataloging rather than full governance, with a connector library spanning legacy ETL and enterprise BI tools.
Key features
-
Cross-system lineage. Traces data across ETL, database, and BI layers in multi-vendor estates without manual mapping.
-
60+ native connectors. Covers legacy ETL such as Informatica, SSIS, Talend, DataStage, and SAS DI alongside Tableau, Power BI, Cognos, and MicroStrategy.
-
Reverse impact analysis. Works backwards from a report field to find every upstream source feeding it.
-
Fast deployment. Runs as SaaS with no-code setup, with first lineage typically available within a day.
-
Data catalog and discovery. Documents technical assets and supports search across mapped systems.
Pros
-
Connector coverage across legacy ETL and enterprise BI is unusually broad for a specialist tool.
-
Reviewers single out support responsiveness and how fast the tool goes live.
Cons
-
Scope stops at lineage and cataloging. Quality, policy, and access control need separate tools.
Best fit: BI and ETL-heavy teams who want lineage across a multi-vendor reporting stack quickly, without buying a full governance platform.
Why column-level lineage keeps showing up as the weak point
Read the nine entries back to back, and one pattern repeats. Atlan cannot filter lineage by source. Collibra struggles once an estate mixes tools. Informatica reviewers find the lineage view hard to read. Alation carries lineage limitations as a review tag. Microsoft supports column-level lineage only for specific sources. Five independent reviewer bases, one shared complaint.
The reason is that table-level lineage answers a different question than the one people ask. Knowing a report depends on a table tells you nothing about which of its forty columns broke.
Our guide to column-level data lineage covers how that distinction plays out in practice, including how to test for it during an evaluation.
How automated data lineage tools build the map
Every platform in this comparison describes itself as automated. The word covers three methods with different failure modes, and knowing which one a tool uses tells you more than any feature list.
1. Manual documentation is accurate on the day someone writes it. Each schema change after that widens the gap between the diagram and production, which is why most lineage projects that start in a spreadsheet end there.
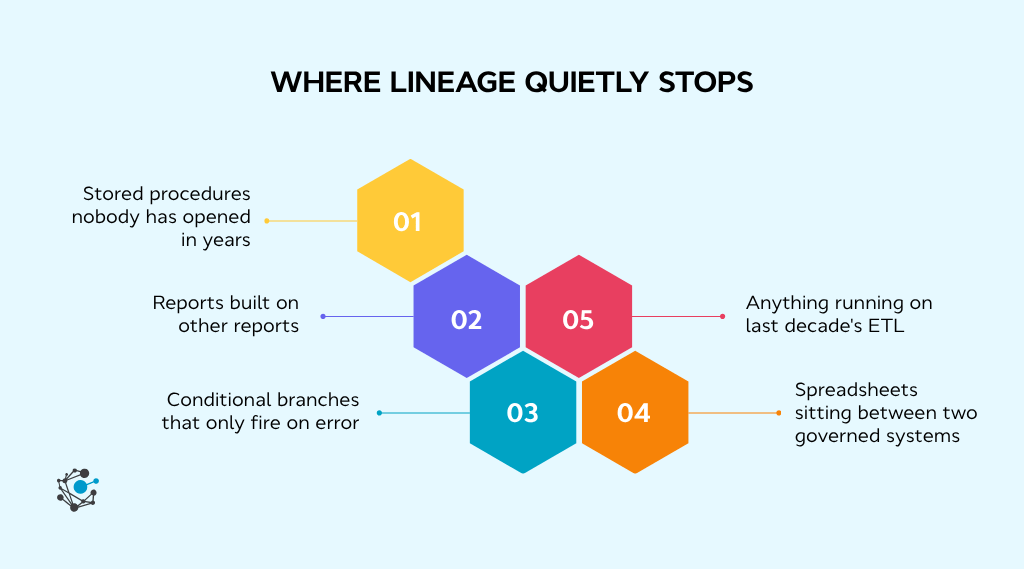
2. Runtime and query log parsing watches what executed. Setup is fast, and results are accurate for common paths, though the map only contains queries that ran during the observation window. A quarterly reconciliation job or an error-handling branch that rarely fires stays invisible.
3. Source code parsing reads the transformation logic directly. Stored procedures, ETL definitions, and reporting queries get analyzed whether or not they ran recently, so infrequent paths still appear in the graph.
Most platforms blend these methods, which makes lineage automation something to assess system by system rather than as a single yes or no. A tool might parse warehouse code properly and fall back to log scraping for the BI layer, and the difference surfaces as a lineage graph that stops at the dashboard boundary.
OvalEdge builds lineage through automated source code parsing across its 170+ connectors, reading SQL, PL/SQL, stored procedures, ETL definitions, and BI models rather than inferring flow from query history.
OvalEdge expert insight: Automation is not one capability. Ask a vendor which systems they parse and which they observe, then check that list against where your regulated data lives.
What governance and compliance teams need from lineage
Governance teams ask more of lineage than engineers do. An engineer needs the map to debug a pipeline. A governance lead needs it to answer a question under scrutiny and leave something that stands up afterwards. Four capabilities separate the two.
Column-level resolution across every regulated system
Audit questions arrive at the field, and table-level lineage settles nothing about which column carried the disputed number. Coverage matters more than depth, since a tool that resolves to the column in your warehouse and stops at the table in legacy ETL leaves the gap where regulated data sits.
An evidence trail, not a screenshot
Diagrams show the current state. Governance work needs a record of what lineage showed when a decision was made. Ask each vendor whether lineage history is retained or overwritten as pipelines change.
Business context attached to technical lineage
An auditor asking about active customers needs the definition, the owner, and the calculation joined to the flow. Lineage that lives apart from a glossary forces someone to reassemble that context by hand every time.
Policy and classification connected to the graph
Knowing where sensitive data travels helps only if controls follow it. Stronger platforms tie classification and access policy to the metadata driving lineage, so a newly discovered PII column inherits the rules covering it.
Regulation reinforces all four.
DORA has applied since January 2025 across more than 22,000 financial entities, per the European Banking Authority, and allows four hours from classifying a major ICT incident to initial notification.
The EU AI Act requires training and testing data for high-risk systems to sit under documented governance, with non-compliance carrying up to €15 million or 3% of turnover, not the €35 million ceiling commonly quoted, which applies only to prohibited practices. Neither names lineage. Both set deadlines that make manual tracing impractical.
OvalEdge connects column-level lineage to sensitive data classification and fine-grained access controls in one platform, so classification, policy, and flow share the same metadata.
How to choose a data lineage tool for your environment
Scoring criteria tell you how the tools compare. Choosing between them depends on what your estate already contains and what fails when lineage falls short. Five environments below cover most buying decisions, and the last question applies regardless of which one you land in.
1. Regulated enterprises with audit obligations
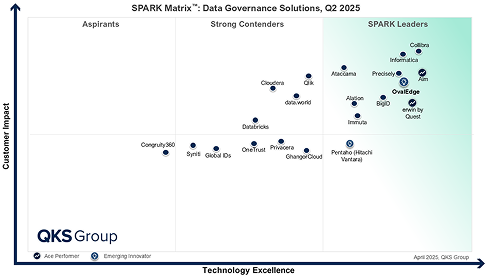
Collibra, Informatica, and OvalEdge all fit here, each covering the four capabilities above with different trade-offs on cost and administration. Run the evaluation against the weakest system in your estate rather than the strongest, since that is where coverage gaps surface.
2. Cloud-native teams on dbt, Snowflake, or Databricks
Atlan is built for this shape of stack, and lineage arrives with the catalog instead of as a separate project. Before committing, check whether you also need lineage for anything outside the warehouse, because that boundary is where cloud-native catalogs stop.
3. Microsoft-centric estates
Purview comes bundled with licensing you probably already hold, which makes it the cheapest starting point by some distance. Confirm which of your sources support column-level lineage first. If regulated data sits outside Azure SQL Database, you will need something alongside it.
4. Hybrid estates carrying legacy ETL
Coverage matters more than interface here. Informatica, Manta, and Cloudera Data Lineage all parse older systems that cloud-native catalogs cannot read. OvalEdge covers the same ground through source code parsing while keeping catalog and glossary in one product, which cuts the number of tools to administer.
5. Engineering-heavy teams weighing build against buy
Open source is a real option when you have platform engineers to run it. The license costs nothing, and the operation costs a person. Price that headcount against commercial licensing before assuming the free route comes out cheaper.
Whichever direction you take, adoption decides the outcome more than features do.
Did you know? OvalEdge keeps lineage inside the same data catalog as glossary and ownership, so analysts read the graph without an engineer translating it. Our guide to data lineage best practices covers the rollout decisions that follow the purchase.
Conclusion
Nine platforms, and the honest summary is that no single one wins. Collibra and Informatica hold up under audit pressure. Atlan suits teams already living in dbt and Snowflake. Purview costs the least if your data sits in Azure. Manta and Cloudera Data Lineage read legacy systems the modern catalogs cannot.
What runs through all nine is the same weakness. Table-level lineage answers a different question than the one people ask when a number looks wrong, and reviewers of five separate platforms say so independently. Test for that gap during evaluation rather than after.
The practical version of that test takes ten minutes. Pick one field that appears in a report your finance team trusts, and ask each vendor to trace it back to origin using your data. Feature lists rarely survive the exercise, and the platform that handles your messiest system is usually the one worth shortlisting.
OvalEdge parses source code across 170+ connectors to build column-level lineage, with catalog, glossary, and access controls in the same platform.

Book a demo to see how far it traces across your stack.