Data management adoption is widespread, but maturity has not kept pace.
EDM Association Global Data Management Benchmark Report 2026 states that 89% of organizations have an active data management initiative, yet only 39.9% have achieved or enhanced capability in data governance.
That maturity gap is increasing interest in AI-powered open-source data lineage tools that can automate discovery, classification, lineage extraction, and impact analysis. Yet AI capabilities vary considerably. Some platforms use ML for metadata enrichment, while others primarily provide the lineage foundation that downstream AI systems can consume.
This guide compares nine leading options across AI and automation capabilities, column-level lineage, integration depth, governance support, deployment complexity, and enterprise readiness.
AI-powered and open-source data lineage tools at a glance
AI capabilities vary considerably across data lineage platforms. Some use AI or machine learning for metadata discovery, classification, enrichment, and anomaly detection, while others provide lineage infrastructure that can support downstream AI applications.
Here is how the nine tools compare across lineage coverage, AI/ML capabilities, licensing, and best fit.
|
Tool |
Primary focus |
Column-level lineage |
AI / ML features |
License |
Best for |
|
OvalEdge |
Governed enterprise lineage |
Yes |
AI-powered discovery, classification, metadata enrichment |
Commercial |
Enterprise lineage with governance, quality, compliance, and business context |
|
Open |
Lineage standard |
Via implementations |
Enables downstream AI |
Apache 2.0 |
Standardizing lineage events across data tools |
|
Marquez |
Metadata store + UI |
Partial |
Structured metadata for analysis |
Apache 2.0 |
Storing and visualizing OpenLineage events |
|
DataHub |
Metadata platform |
Yes |
ML-assisted ownership and tagging |
Apache 2.0 |
Large-scale metadata management and lineage |
|
Open |
Unified metadata platform |
Yes |
ML tagging and anomaly detection |
Apache 2.0 |
Metadata, lineage, quality, and governance |
|
Apache Atlas |
Governance + classification |
Yes |
No native AI |
Apache 2.0 |
Hadoop-centric and regulated environments |
|
Egeria |
Federated metadata exchange |
Partial |
No native AI |
Apache 2.0 |
Federating metadata across multiple platforms |
|
OpenDataDiscovery (ODD) |
ML pipeline observability |
Yes |
ML pipeline and model tracking |
Apache 2.0 |
AI/ML pipeline lineage and observability |
|
Spline |
Spark execution lineage |
Yes, Spark only |
No native AI |
Apache 2.0 |
Automated lineage for Spark environments |
Reading this table: AI capabilities are not uniform across these platforms. Some use AI or ML directly for metadata enrichment, classification, or anomaly detection, while others provide lineage metadata that can support downstream AI systems. OvalEdge is the commercial enterprise option; the remaining eight platforms are open-source.
Top AI-powered and open-source data lineage tools
The platforms below represent different approaches to modern data lineage, from AI-assisted metadata management and ML pipeline observability to lineage standards and specialized execution tracking.
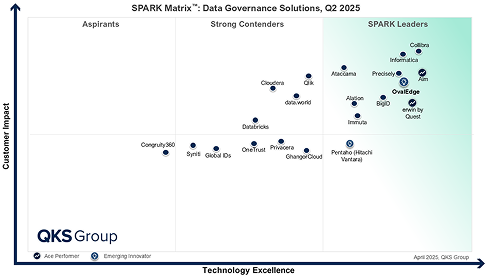
OvalEdge is included as the commercial enterprise option for organizations looking for automated lineage combined with governance, quality, compliance, and business context.
1. OvalEdge: Best enterprise alternative for governed data lineage
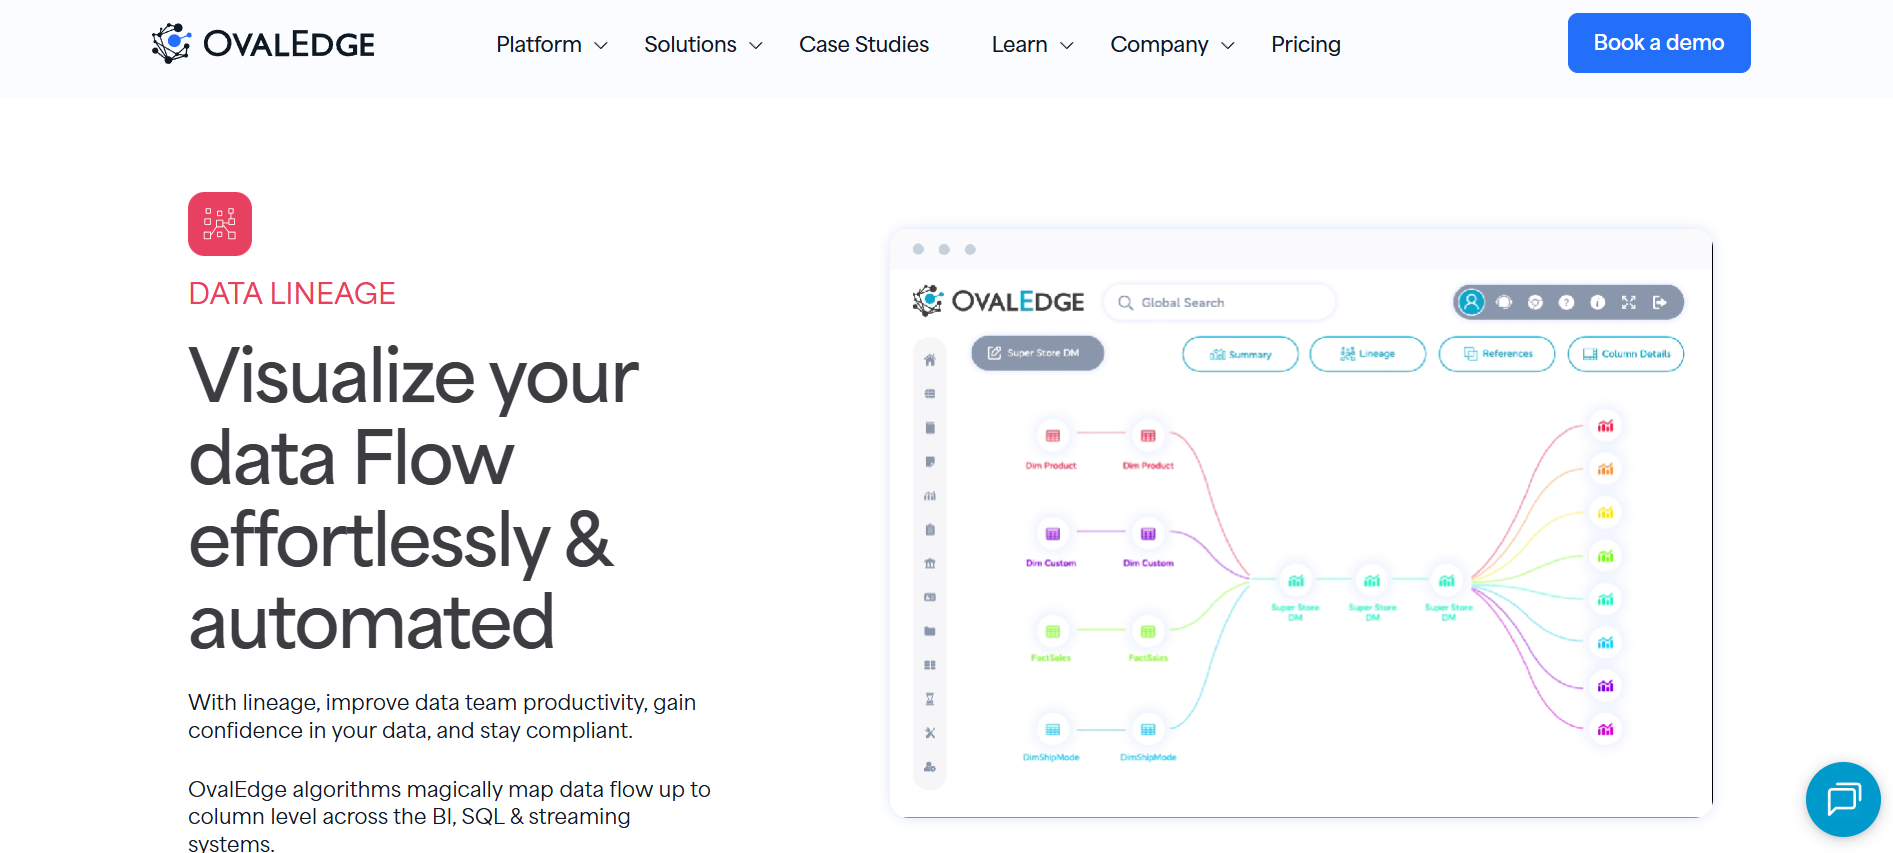
OvalEdge is an enterprise data governance and lineage platform that connects technical data flows with the business and governance context surrounding them. Its Enterprise Context Graph brings lineage, definitions, ownership, data quality, classifications, and policies together in a governed environment.
Key features
-
Automated column-level lineage: Parses source code and transformation logic to map field-level data movement.
-
End-to-end traceability: Follows data from source systems through transformations to reports and analytics.
-
Impact analysis: Identifies upstream and downstream dependencies before teams make data changes.
-
Sensitive data tracking: Traces classified and regulated information across systems.
-
Integrated governance: Connects lineage with glossary, quality, ownership, classification, and policy metadata.
Best fit
Best for enterprises that need lineage to support governance, compliance, data quality, and business use cases across complex data environments.
How OvalEdge stands out
Many lineage tools are designed primarily to show where data moves. OvalEdge focuses on making that lineage usable for decisions and governance.
The Enterprise Context Graph gives each lineage relationship additional context, such as what the data means, who owns it, whether it meets quality expectations, and which policies apply. This allows engineering teams to investigate dependencies while governance and compliance teams work from the same connected information.
That becomes particularly valuable at enterprise scale, where tracing a column is only part of the problem. Teams also need to determine whether downstream assets are affected, whether sensitive information is involved, and who is responsible for resolving an issue.
OvalEdge in action: Bedrock
Bedrock previously relied on manually mapped lineage to understand data flows and integrations. With OvalEdge's auto-lineage capabilities, the team could trace data across its environment and investigate data quality issues closer to their source.
Automating lineage saved Bedrock months of manual work while providing a more comprehensive view of its data flows and integrations. The result demonstrates the practical advantage of replacing manually maintained lineage documentation with automated, continuously usable lineage.
Book an Enterprise Data Lineage Demo to see how OvalEdge can bring automated lineage, governance, and business context together.
2. OpenLineage
OpenLineage is an open standard and API specification for collecting lineage metadata as data jobs execute. It provides a common lineage event model that platforms such as Airflow, Spark, dbt, Flink, and Dagster can use to exchange lineage information consistently.
Key features
-
Real-time lineage events: Captures metadata when jobs start, complete, or fail.
-
Framework-agnostic standard: Provides a consistent lineage model across different data technologies.
-
Pipeline integrations: Works with Airflow, Spark, dbt, Flink, Dagster, and other frameworks.
-
Standardized metadata exchange: Helps different systems produce lineage information in a common format.
-
Extensible ecosystem: Supports a growing integration ecosystem backed by the Linux Foundation's LFAI & Data initiative.
Pros
-
Open and vendor-neutral standard
-
Strong pipeline interoperability
-
Growing integration ecosystem
Cons
-
No built-in UI or storage
-
Integration depth varies by platform
Best fit
Best for engineering teams that want to standardize lineage event collection across multiple pipeline and processing technologies while choosing their own storage and visualization layer.
3. Marquez
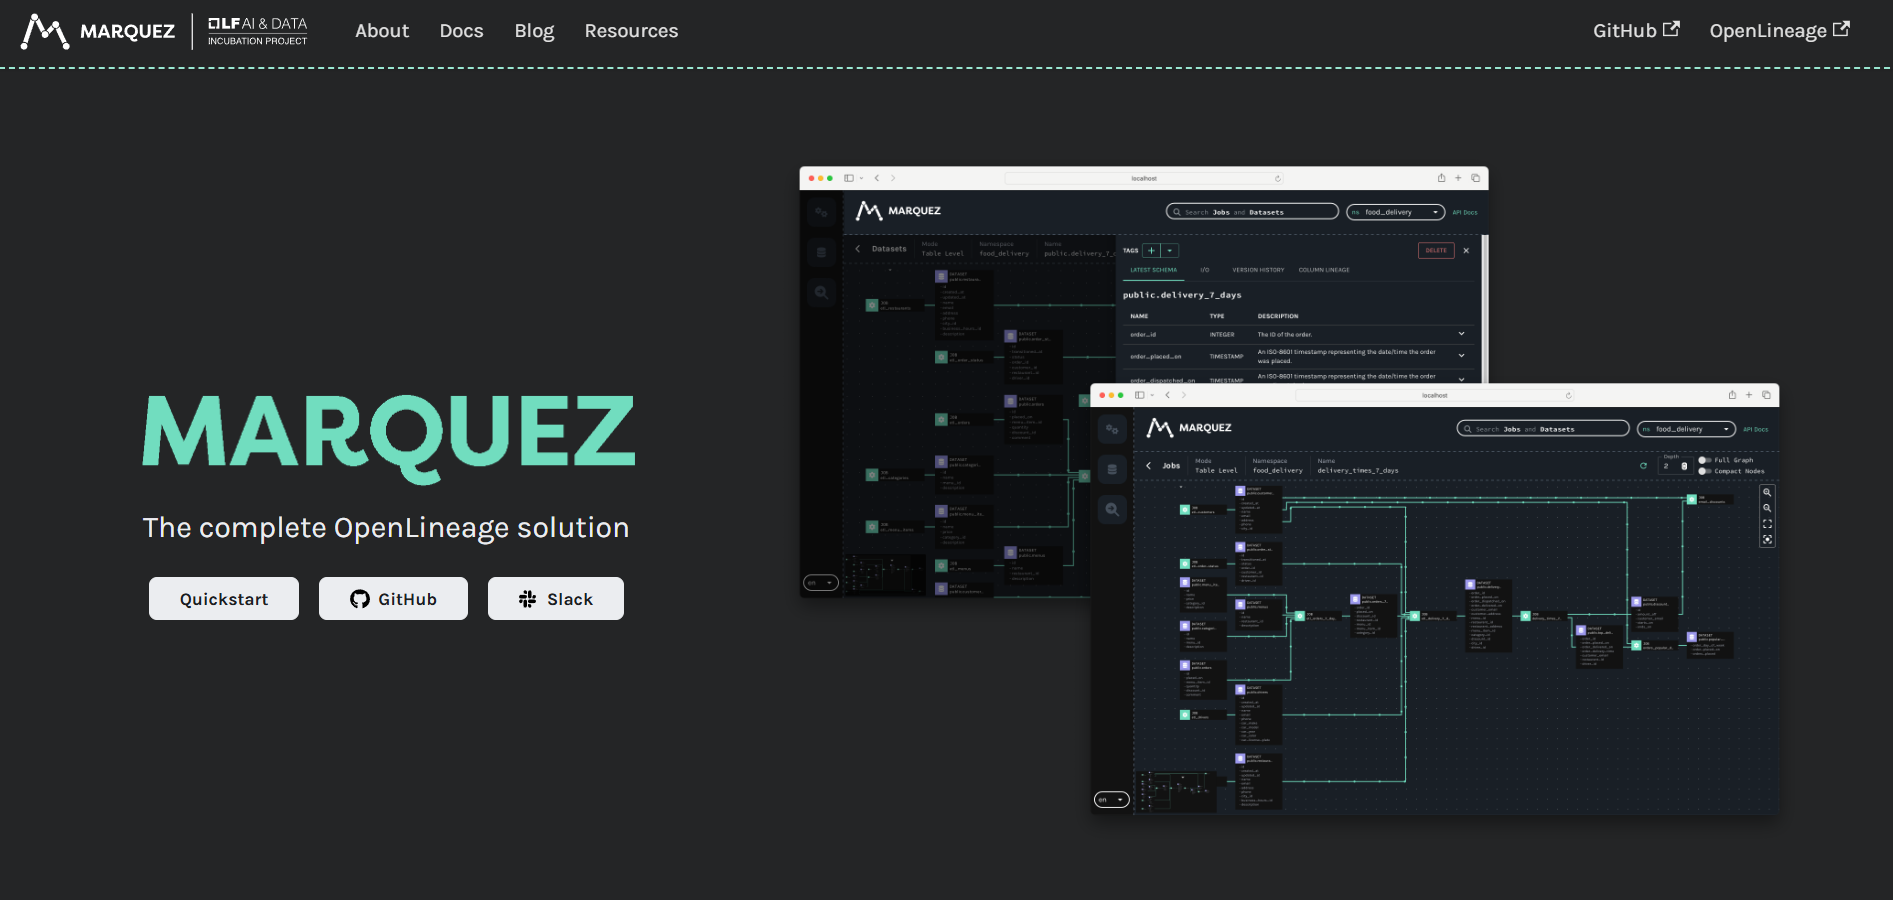
Marquez is the reference implementation for OpenLineage. It adds the metadata repository, REST API, and web interface required to store and explore the lineage events captured through OpenLineage.
Key features
-
Metadata repository: Stores datasets, jobs, and associated lineage metadata.
-
Dataset versioning: Maintains versions of datasets and jobs as pipelines change.
-
Visual lineage: Provides a web interface for exploring pipeline relationships.
-
OpenLineage ingestion: Consumes OpenLineage events from compatible systems.
-
REST API: Makes stored metadata and lineage information programmatically accessible.
Pros
-
Native OpenLineage support
-
Built-in lineage visualization
-
Straightforward metadata repository
Cons
-
Partial column-level lineage
-
Limited governance capabilities
Best fit
Best for teams already adopting OpenLineage that need a practical backend for storing, querying, and visualizing their lineage events.
4. DataHub
Originally developed at LinkedIn, DataHub is a general-purpose metadata platform combining lineage, search, discovery, and schema history. Its broad functionality makes it suitable for teams that want lineage within a larger metadata management environment.
Key features
-
Column-level lineage: Tracks field-level dependencies and transformations across connected systems.
-
Metadata discovery: Centralizes metadata for search and exploration.
-
ML-assisted enrichment: Suggests ownership and metadata tags using machine learning.
-
Broad integrations: Supports Snowflake, BigQuery, dbt, Airflow, Kafka, and other technologies.
-
Schema history: Maintains metadata changes that help teams understand how data assets evolve.
Pros
-
Strong column-level lineage
-
Large open-source community
-
Extensive integration ecosystem
Cons
-
Infrastructure-heavy deployment
-
Can overwhelm smaller teams
Best fit
Best for larger data teams that need scalable metadata management and cross-platform lineage across complex modern data stacks.
5. OpenMetadata
OpenMetadata is a unified open-source metadata platform covering data discovery, lineage, quality, and governance. Its broader feature set makes it one of the closest open-source options to a full data catalog and governance platform.
Key features
-
Column-level lineage: Extracts detailed lineage from SQL, dashboards, and pipelines.
-
Automated lineage extraction: Reduces manual mapping across supported data systems.
-
Data quality: Includes testing, profiling, and anomaly detection capabilities.
-
ML-assisted tagging: Uses machine learning to support metadata classification and enrichment.
-
Governance workflows: Provides glossary management, approvals, and role-based access controls.
Pros
-
Broad metadata functionality
-
Built-in data quality capabilities
-
Strong governance coverage
Cons
-
Some connectors are still maturing
-
Requires ongoing infrastructure maintenance
Best fit
Best for teams looking for an all-in-one open-source platform covering lineage, metadata discovery, data quality, and basic governance.
6. Apache Atlas
Apache Atlas is a governance-focused open-source metadata and lineage platform built around the Hadoop ecosystem. Its integration with Apache Ranger makes it particularly relevant for organizations where classification, policy enforcement, and compliance are major requirements.
Key features
-
Detailed lineage: Captures dependencies across supported Hadoop technologies.
-
Column-level tracing: Provides granular lineage within supported environments.
-
Data classification: Categorizes data using its built-in classification framework.
-
Business glossary: Connects technical assets with governed terminology.
-
Ranger integration: Works with Apache Ranger for policy enforcement and access controls.
Pros
-
Strong governance capabilities
-
Deep Hadoop integration
-
Supports policy enforcement
Cons
-
Limited modern cloud coverage
-
Dated user interface
Best fit
Best for Hadoop-centric or regulated environments that prioritize governance, classification, lineage, and access-policy integration.
7. Egeria
Egeria takes a federated approach to metadata management. Rather than requiring every system to move metadata into a single repository, it enables multiple platforms to retain their metadata while exchanging lineage and governance information.
Key features
-
Metadata federation: Exchanges metadata across heterogeneous environments.
-
Open metadata types: Provides standardized models for sharing metadata.
-
Integration framework: Connects different metadata platforms and tools.
-
Governance engine: Supports automated metadata management and governance actions.
-
Distributed architecture: Allows participating systems to retain their individual metadata stores.
Pros
-
Strong federation model
-
Suitable for heterogeneous stacks
-
Built-in governance framework
Cons
-
Complex for smaller environments
-
Smaller integration ecosystem
Best fit
Best for large organizations that need to federate metadata and governance information across multiple tools, platforms, or cloud environments.
8. OpenDataDiscovery (ODD)
OpenDataDiscovery sits between data observability and data lineage, with a particular focus on ML and AI pipelines. It traces data from source systems through feature stores and model outputs while adding pipeline observability.
Key features
-
Full-stack lineage: Traces data from ingestion through downstream ML outputs.
-
Column-level lineage: Provides granular tracking across supported pipelines.
-
ML pipeline tracking: Follows data through machine learning workflows.
-
Model awareness: Captures experiment and model-versioning context.
-
Open collectors: Allows teams to extend metadata collection to custom sources.
Pros
-
Strong ML pipeline focus
-
Extensible collector architecture
-
Combines lineage and observability
Cons
-
Narrower warehouse integrations
-
Limited governance controls
Best fit
Best for data science and ML engineering teams that need lineage and observability across machine learning pipelines rather than traditional BI-focused environments.
9. Spline
Spline is a specialized lineage platform built for Apache Spark. It automatically captures Spark execution plans as jobs run, providing detailed transformation lineage without requiring developers to manually instrument individual jobs.
Key features
-
Automatic Spark lineage: Captures lineage directly from Spark execution plans.
-
Column-level tracking: Traces field-level transformations within Spark workloads.
-
Low-code instrumentation: Attaches to Spark jobs without extensive application changes.
-
Execution visibility: Records transformation information as Spark workloads execute.
-
Visual lineage graph: Provides a UI for exploring captured transformation chains.
Pros
-
Strong Spark specialization
-
Automatic lineage capture
-
Lightweight implementation
Cons
-
Limited to Spark workloads
-
Smaller open-source community
Best fit
Best for Spark-heavy data environments that need automatic, detailed lineage without deploying a broader metadata management platform.
How AI-powered and open-source data lineage tools compare
Feature lists alone do not show how well a lineage platform will perform in production. When comparing AI-powered and open-source data lineage tools, three areas deserve closer attention: AI and automation capabilities, lineage coverage, and governance readiness.
1. AI and automation capabilities
AI maturity varies widely across the nine options. OvalEdge applies AI-assisted capabilities to metadata discovery, classification, and enrichment while connecting lineage with broader governance context. DataHub uses ML to support metadata enrichment, while OpenMetadata combines ML-assisted tagging with anomaly detection.
OpenDataDiscovery focuses more specifically on ML pipeline and model tracking. OpenLineage, Marquez, Apache Atlas, Egeria, and Spline provide lineage foundations or specialized capabilities without making native AI their primary focus.
This distinction matters because AI readiness can mean different things. Teams should determine whether they need AI-assisted metadata management, automated lineage extraction, ML pipeline traceability, or lineage metadata that can provide context to downstream AI systems.
2. Lineage and integration coverage
OvalEdge, OpenMetadata, and DataHub provide broader coverage for organizations operating across multiple data systems. Apache Atlas remains strongest within Hadoop environments, while Spline specializes in Spark execution lineage.
OpenLineage standardizes lineage events across compatible frameworks, while Marquez provides a repository and interface for storing and exploring those events.
The right option therefore depends on whether the organization needs enterprise-wide lineage across a heterogeneous stack or specialized lineage for specific pipelines and processing technologies.
3. Governance and AI readiness
AI applications increasingly depend on context beyond technical data relationships. Teams may need to determine what data means, who owns it, whether it meets quality requirements, how sensitive it is, and which policies govern its use.
OvalEdge connects these signals through its Enterprise Context Graph. Among open-source options, Apache Atlas emphasizes governance and classification, while OpenMetadata combines lineage with quality and governance workflows. DataHub extends lineage into broader metadata management.
For AI initiatives, teams should evaluate whether lineage metadata can provide enough context to identify data that is trusted, governed, and appropriate for downstream consumption.
Where AI-powered open-source data lineage tools fall short
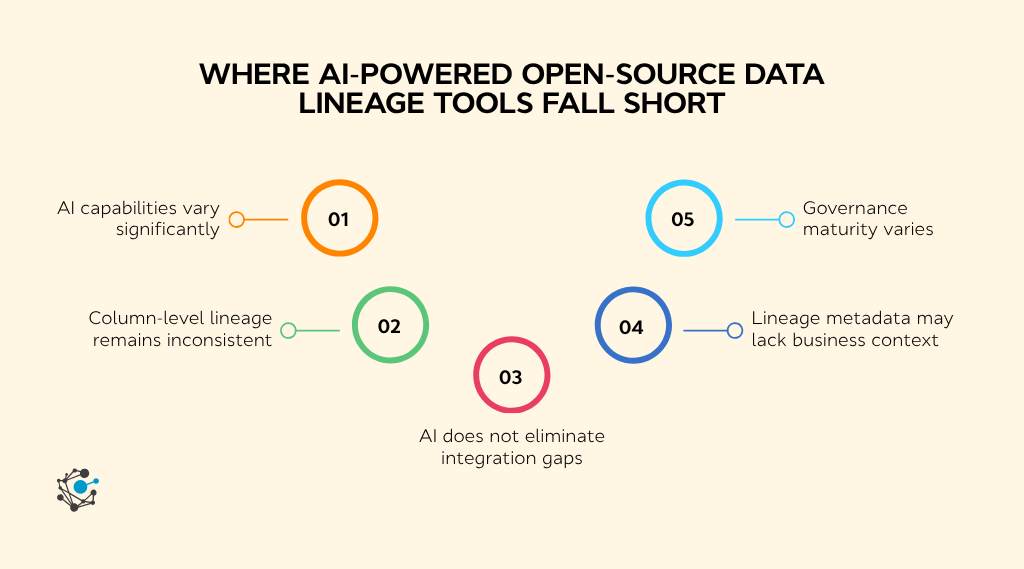
AI and automation are expanding what lineage platforms can do, but several limitations remain across the open-source landscape.
AI capabilities vary significantly. Some platforms offer ML-assisted tagging, anomaly detection, or metadata enrichment, while others have little or no native AI functionality. Advanced capabilities such as context-aware discovery, intelligent classification, and governed AI context remain less common.
For a closer look at automation across open-source and commercial platforms, see this breakdown of automated data lineage tools and what they actually automate.
Column-level lineage remains inconsistent. DataHub and OpenMetadata provide strong field-level capabilities across supported integrations, while Apache Atlas offers granular lineage within Hadoop environments. Spline specializes in Spark. OpenLineage and Egeria depend more heavily on implementation and connector depth.
AI does not eliminate integration gaps. Automated enrichment provides limited value when a platform cannot see important parts of the data stack. Organizations should evaluate databases, warehouses, ETL systems, orchestration platforms, BI tools, and AI pipelines together rather than assessing AI features independently.
Lineage metadata may lack business context. A lineage graph can show that one field feeds another without explaining what the field means, whether its quality is acceptable, who owns it, or whether an AI application should use it.
Governance maturity varies. AI-assisted lineage still requires ownership, classifications, policies, and controls. Teams evaluating these requirements should map tools against a structured data lineage governance framework before committing to a platform.
When teams outgrow AI-powered open-source lineage
Open-source lineage can work well for focused stacks, engineering-led implementations, experimentation, and environments where teams have the resources to configure and maintain the required components.
Complexity increases as lineage must span SAP, Salesforce, Snowflake, BigQuery, transformation pipelines, BI platforms, and AI workloads. AI-assisted tagging or discovery cannot compensate for missing metadata or disconnected lineage across these environments.
Requirements also change as lineage becomes relevant to governance and AI. Teams may need to know whether a dataset is certified, which business definition applies, whether quality thresholds are being met, who owns an asset, and whether an AI system is permitted to consume it.
At that stage, lineage becomes part of the context infrastructure supporting trusted enterprise data and AI use.
When AI-powered open-source lineage is not enough: The enterprise path
Open-source platforms provide valuable building blocks for lineage, metadata management, and AI experimentation. Enterprise environments introduce additional requirements around cross-system coverage, governance, quality, sensitive data, and business context.
OvalEdge addresses these requirements through its Enterprise Context Graph, connecting lineage with contextual signals required to interpret and govern enterprise data:
-
Parses SQL, ETL scripts, and BI logic to automate column-level lineage
-
Connects lineage with quality, classification, ownership, and business definitions
-
Tracks regulated data as it moves across systems
-
Refreshes lineage as underlying metadata changes
-
Makes governed metadata available as context for enterprise AI use cases
This approach follows the principles of end-to-end data lineage architecture, where lineage extends from source and transformation layers through downstream consumption.
For teams moving beyond OpenMetadata, DataHub, or specialized open-source implementations, the next requirement is often a governed context layer that makes lineage useful across data, governance, compliance, and AI workflows.
Conclusion
AI is raising expectations for what data lineage must provide. Open-source platforms offer strong foundations for lineage capture, metadata management, Spark tracing, ML observability, and specialized requirements, but their AI capabilities and enterprise coverage vary considerably.
As organizations scale AI, lineage also needs to carry the context required to determine whether data is trusted, governed, and appropriate for use. That includes quality, ownership, classification, policies, and business meaning.
For teams that need to move beyond assembling open-source components, OvalEdge connects automated column-level lineage with governance and business context through its Enterprise Context Graph.

Book an Enterprise Data Lineage Demo.