A semantic layer was built to make five dashboards agree on one revenue number. It was never built to tell an AI agent which revenue number to trust, for whom, and under what rules.
The gap is the context layer vs the semantic layer question. A semantic layer standardizes what a metric means across enterprise data. A context layer governs when and how an AI agent can use it. It adds lineage, ownership, quality, and sensitivity, which are not held in the metric definition.
What changed is the consumer. For years, a person worked between the data and the action, so a clean definition was enough. Now agents read a definition and act on it directly, which means governance has to travel with the metric at the moment of use.
The two are different problems, not one problem with two names. This post defines each layer, compares them, weighs which one AI workloads need, and shows where governance fits. The harder question runs underneath both: neither layer creates governed metadata on its own.
What is a semantic layer?
A semantic layer is a business logic layer that sits between raw warehouse data and the tools people use to query it. It maps technical fields to agreed metric definitions, so every dashboard, report, and Structured Query Language (SQL) query returns the same number for the same metric.
In practice, it translates a column like txn_amt into Transaction Amount and cust_id into Customer ID, then attaches the approved formula behind each one. A request for revenue resolves to one governed calculation instead of whatever each analyst types by hand.
Teams build this layer with tools like dbt MetricFlow, Looker (LookML), AtScale, and Cube, or with the native semantic models inside Snowflake and Databricks.
A semantic layer is not a data catalog, a knowledge graph, or a governance platform. It settles how a metric is calculated and stops there. It says nothing about who owns that metric, how long the definition stays valid, or whether the data is safe to expose.
That scope works well for business intelligence (BI) dashboards and key performance indicator (KPI) reporting, where a person reads the result and applies judgment. It becomes one layer among several the moment an AI agent acts on the output with no human in the loop.
What is a context layer?
A context layer is a governance layer that sits above the semantic layer and decides how data can be used, not only what it means. Most of what it needs already exists inside the enterprise as glossaries, lineage maps, ownership records, classifications, and quality rules.
The context layer packages that governance into machine-readable signals an agent can read at runtime, which is why it is better understood as existing governance made live than as a brand-new system to procure.
Take a revenue metric. The semantic layer says how revenue is calculated. The context layer adds where the number came from and who is accountable for it, then carries the sensitivity, quality, and validity rules an agent needs before it acts. Typically, a human analyst fills these gaps with judgment. An agent has none, so the context layer supplies them as explicit signals.
For example, a bank’s “high-risk counterparty” has different thresholds across credit, compliance, and trading desks. An agent pulling a counterparty list without knowing which threshold applies produces a risk report that is either dangerously lenient or operationally paralyzing.
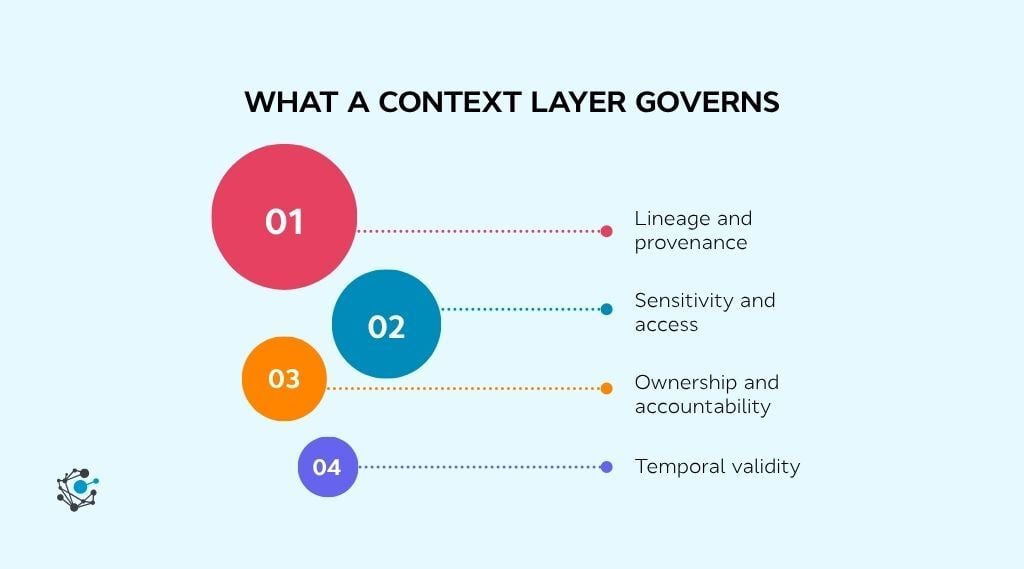
Together, the five signals below answer one question: Can the AI safely use this data? Each covers something the semantic layer leaves open:
-
Lineage: the source systems, transformations, and quality checks behind every metric, so an answer can be traced rather than trusted on faith.
-
Sensitivity: classifications like restricted, internal, or regulated that block an agent from exposing protected data before it reaches output.
-
Ownership: a named owner for every metric and policy, so a person enters the loop when something breaks.
-
Quality: freshness and reliability signals that tell the agent whether to answer with confidence, attach a warning, ask the user for clarification, or hold off entirely. A clean definition of stale data is still a wrong answer waiting to happen. Automated data quality checks surface these freshness and reliability gaps before an agent inherits them.
-
Temporal validity: valid-from dates and version history, so an agent applies the rule that fits the period instead of an expired one.
Put together, these signals do more than describe the data. They shape behavior. A context layer is what lets an agent decide whether it should answer at all, which definition applies, whether the result is trustworthy, whether this user is allowed to see it, and when it should escalate to a person.
A context layer consumes the semantic layer’s metric definitions and controls how an agent uses them. The distinction is where most AI data infrastructure decisions go wrong, because teams buy a context layer expecting it to define metrics it was never built to define. The next section breaks down the difference.
Context layer vs semantic layer: the key differences
The table below maps the split across the dimensions that matter when you choose between context and semantic layer, whether to build either, or run both.
|
Dimension |
Semantic layer |
Context layer |
|
Primary purpose |
Define metrics consistently |
Govern how metrics are used |
|
What it models |
Metric formulas and business logic |
Lineage, ownership, sensitivity, quality, and validity rules |
|
Primary consumers |
BI tools, dashboards, analysts |
AI agents and automated workflows |
|
Governance scope |
Calculation only |
Access, sensitivity, quality, accountability, and time validity |
|
Runtime behavior |
Returns a defined metric |
Decides whether the agent should answer, warn, ask, refuse, or escalate |
|
Relationship |
One input the context layer consumes |
The layer that wraps and governs the semantic layer |
|
Freshness model |
Updates when a definition changes |
Tracks validity windows and versions over time |
|
Failure mode |
Two teams report different numbers |
An agent acts on data it should never have touched |
|
Key technologies |
dbt MetricFlow, Looker, AtScale, Cube |
Data catalogs, policy engines, governance platforms |
Where the two layers overlap
The two layers share the same starting point, which is why they get confused. Both depend on accurate metric definitions, and both cut the guesswork in how data gets used. A semantic layer is one of the inputs a context layer reads from, so a strong semantic layer makes the context layer more reliable.
The overlap ends at the purpose. A semantic layer settles the math and hands off a clean number. A context layer takes that number and decides whether an agent can act on it, for whom, and under which policy. One produces a trusted definition. The other produces a trusted decision.
For years, that second job went unnoticed, because a person did it by instinct; the distinction only started to matter once AI agents began acting on the number with no one in between.
Why the distinction matters now
AI agents remove the human review step that made a semantic layer sufficient on its own. For a decade, an analyst caught stale or restricted data before it reached a decision.
An agent reads a metric and acts on it in one motion, with no instinct or question about whether the source is stale or the data is restricted.
Gartner’s 2026 Data and Analytics Predictions estimate that by 2030, half of all AI agent deployment failures will come from insufficient runtime governance enforcement.
The semantic layer still gives it a correct definition, not whether using that definition is safe. The context layer closes the gap, which is why the question moved from optional to architectural the moment agents started acting on enterprise data without a human in the loop.
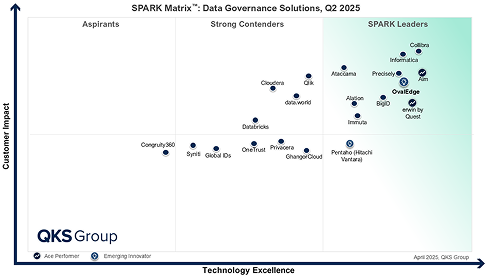
At OvalEdge, we believe AI does not reduce the need for data governance. It raises the cost of weak governance. The work is connecting scattered governance into a unified Enterprise Context Graph. Agents can query it in the flow of a decision.
Semantic layer vs context layer for AI: which one to use when
Use a semantic layer when people consume the output. Add a governed context over the top when AI agents act on it. The deciding factor is not the size of your data. It is who reads the result, and whether anyone checks it before something happens.
A semantic layer is enough when:
-
Analysts and dashboards are the end consumers.
-
A person reviews the number before acting on it.
-
A wrong result means a misread chart rather than an automated action.
You need a context layer on top when:
-
AI agents query data and act with no human reviewing each step.
-
The same metric carries different access rules for different users or teams.
-
A wrong result can trigger a workflow, expose restricted data, or write back to a system.
The gap shows up fast under real conditions. A clean semantic layer hands the agent a correct definition, yet the agent still needs to know which source to trust, what it is allowed to see, and when a definition no longer applies. That is the context layer's job.
Most enterprises never actually pick one. They already run a semantic layer for BI, and they add a context layer once agents start acting on the same data. Building the context layer is a governance job: platforms like OvalEdge connect the catalog, lineage, and access rules that a semantic layer was never meant to hold.
Context layer vs semantic layer in data governance
A semantic layer creates definitional work for a central team, while a context layer pushes governance outward to data owners, security, and compliance. Inside a governance program, the two layers demand different stewardship models, different enforcement mechanisms, and different accountability structures.
1. Stewardship: who maintains what
A semantic layer needs a small group of stewards to keep definitions consistent, so the work concentrates. A context layer pushes stewardship outward. Sensitivity classifications belong to security or compliance, quality thresholds belong to the data owners closest to the source, and ownership records have to name a real person for every metric and policy.
The harder governance question is not how to write these rules once. It is how to keep them current as systems, owners, and regulations change, because a context layer reasoning from a stale rule fails in ways a person would have caught.
OvalEdge expert insight: When a retail loyalty program defines “active member” differently across the app, website, and in-store systems, the semantic layer picks one formula. The context layer tracks which team owns each definition and what happens when they conflict.
2. Policy enforcement: from documented to executable
Most governance policies live as documents that people are expected to follow. A context layer changes the bar, because an agent cannot read a policy PDF and apply judgment. Every rule it needs has to exist as machine-readable metadata: a classification it can check, a threshold it can compare against, and an access rule it can resolve per user.
Governance that was advisory becomes enforceable, and the gap between a written policy and an encoded one becomes the gap between a control that works and one that only looks like it does.
3. Runtime decision-making: governance at the moment of use
The deepest shift is when governance happens. Traditional governance runs before and after the fact through reviews, audits, and access requests. A context layer moves a slice of it into the moment of the decision, where the agent reads the signals and chooses whether to answer, warn, ask, refuse, or escalate.
Governance stops being a periodic checkpoint and becomes a live input to every automated action, which raises the cost of any rule that is missing, wrong, or out of date.
Why neither layer creates governed metadata on its own
Neither layer produces governance. Both consume it. The glossary, lineage, ownership records, quality rules, and policies each layer reads from have to exist underneath first. When the foundation is weak, both fail quietly. A semantic layer standardizes unreliable numbers with precision, and a context layer reasons from incomplete rules. Both failures look like a tool problem and are actually a metadata problem.
The fix is the same foundation for both: a governed data catalog, a maintained business glossary, end-to-end lineage, and active metadata that updates as upstream systems change. Without that foundation, both layers operate on assumptions, and the agents downstream inherit the gaps.
OvalEdge expert insight: Neither layer creates the governed metadata it reads from. For teams building the baseline, the OvalEdge whitepaper lays out a 5-step data governance framework proven across 100+ implementations.
How the context layer and the semantic layer work together
The semantic layer feeds definitions into the context layer, which wraps them with governance signals for AI agents. The two are interdependent, not sequential.
The architecture pattern: how the two layers stack
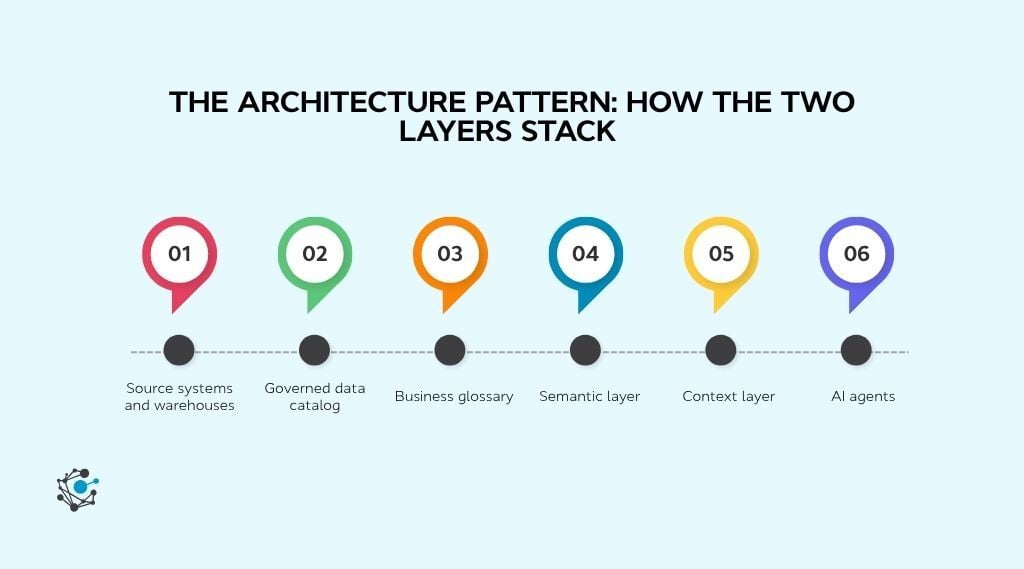
From the bottom up:
-
Source systems and warehouses: Snowflake, Databricks, and operational databases hold the raw data.
-
Governed data catalog: indexes every asset, captures technical and business metadata, and tracks lineage end to end.
-
Business glossary: lives inside the catalog and holds the canonical definitions of business entities.
-
Semantic layer: sits above the catalog, consuming glossary definitions and metric logic through tools like dbt, Looker, AtScale, and Cube.
-
Context layer: wraps the semantic layer and adds the governance signals: lineage from the catalog, ownership from the glossary, sensitivity from the policy engine, quality from the metadata platform, and validity from version history.
-
AI agents: consume the context layer through delivery mechanisms.
At OvalEdge, we believe the layers succeed or fail together. The layers succeed or fail together. A clean metric formula tells nothing if the agent cannot trace its source, and governed lineage is not useful if the metric it tracks was never agreed on. The architecture works only when the foundation underneath is real.
Retrieval-Augmented Generation (RAG), the Model Context Protocol (MCP), and application programming interfaces (APIs) are how context reaches the agent. They move context. They do not make it trustworthy.
Point any of them at weak or ungoverned metadata, and the agent gets the wrong context faster. Each layer has one job and one clear input. Skip the catalog or glossary at the bottom, and every layer above reasons from incomplete information.
What lives underneath: catalog, glossary, lineage, metadata governance
The stack only holds if four foundations are in place: a governed data catalog that inventories every asset with its classifications and owners, and a maintained business glossary the domain teams review on a schedule. Underneath both, column-level lineage runs from source to consumption, and active metadata keeps the whole stack current with freshness signals and change events instead of going stale.
Platforms like OvalEdge connect those four into an Enterprise Context Graph, the governed foundation both layers read from.
Conclusion
The context layer vs semantic layer decision comes down to who consumes your data. If people read the output, the latter is sufficient. If agents act on it, you need a context layer over the top, and that is the more decisive investment because a wrong action costs more than a wrong chart.
Both layers stand or fall on the same foundation: a governed catalog, a maintained glossary, end-to-end lineage, and current metadata. When an Enterprise Context Graph connects these assets into a single queryable structure, your agents inherit governed context instead of assumptions.
Most enterprises already hold this foundation across their catalogs, glossaries, and lineage maps.
OvalEdge connects and activates it through the Enterprise Context Graph, giving both layers a single governed source to read from. See how OvalEdge powers them. Book a demo.