Most teams run a data catalog and some form of lineage tracking as separate systems. That gap shows up fast: compliance audits that take weeks instead of hours, broken dashboards nobody can trace back to a source change, and AI models trained on data nobody can vouch for.
The root cause is almost always the same. Catalog and lineage operate in silos, with no shared context between them. One tells you what data exists and where it lives. The other tells you where it came from and what changed along the way. Without both working together, neither delivers its full value.
This guide covers what each tool does, how they differ, where they overlap, and which one to invest in first, so that you can make an informed decision.
What is data lineage?
Data lineage tracks how data moves, transforms, and flows across systems, from its origin to its final point of use. It gives teams a clear map of every step data takes, making it easier to monitor quality, satisfy compliance requirements, troubleshoot broken reports, and build confidence in the numbers behind dashboards and AI models.
When lineage is missing, diagnosing a broken metric in a board report can take days of back-and-forth across teams. When it is documented, the same investigation takes minutes.
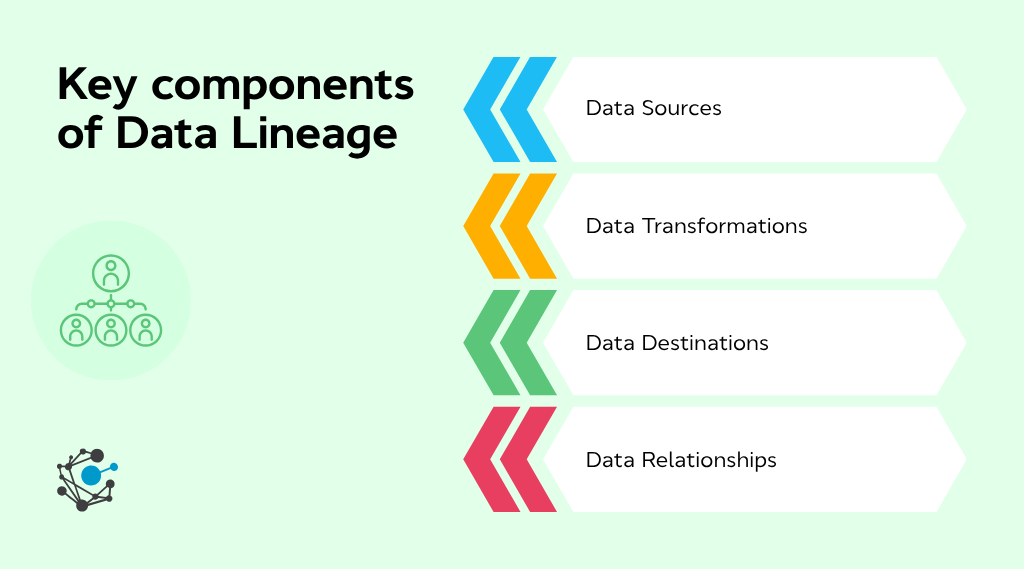
Every lineage map covers four core components:
-
Data sources: Starting points where data originates, including transactional systems, APIs, databases, and third-party applications.
-
Data transformations: Modifications applied along the way, from basic cleansing and deduplication to complex aggregation and metric calculation.
-
Data destinations: Systems where processed data lands for consumption, such as warehouses, BI platforms, analytical dashboards, and machine learning pipelines.
-
Data relationships: Connections between datasets and systems that reveal downstream impact when something upstream changes.
For example, a quarterly revenue dashboard pulls raw transaction records from the CRM and billing system (sources), deduplicates and aggregates them into monthly totals (transformations), loads the result into the data warehouse (destination), and feeds three downstream reports that break if the aggregation logic changes (relationships).
Automated data lineage tools replace the manual spreadsheets and tribal knowledge that go stale the moment a schema changes. Instead of relying on one engineer who happens to remember how a pipeline was built, every stakeholder gets a single, up-to-date view of how data flows through the organization.
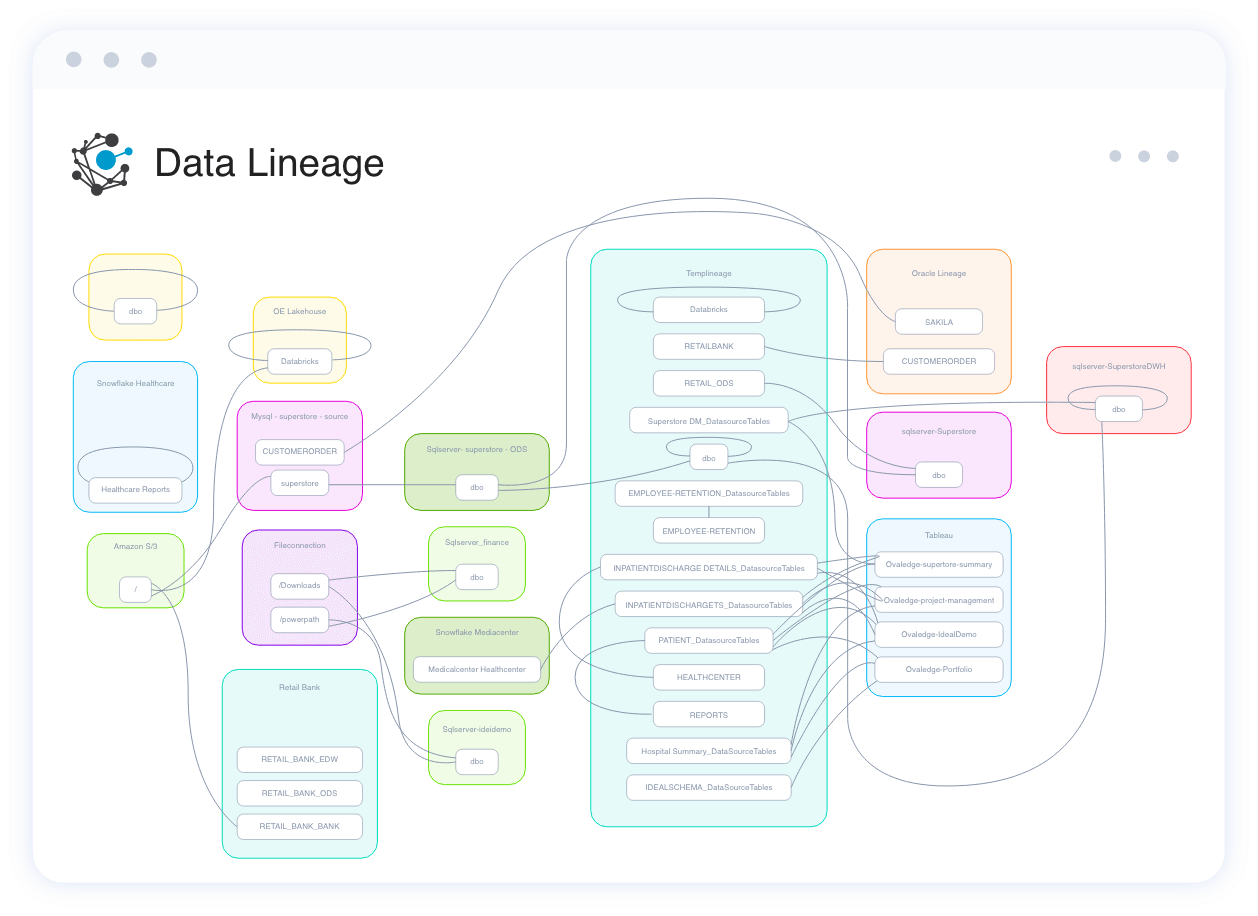
OvalEdge's data lineage gives data teams full visibility into how data moves, transforms, and connects across systems, so they can resolve issues faster, trust what they ship, and prove compliance when it counts.
What is a data catalog?
A data catalog is a searchable inventory of all the data an organization owns. It stores metadata, including definitions, owners, data types, sensitivity tags, and quality scores, so business users, analysts, and engineers can locate datasets, understand their contents, and verify trustworthiness before putting them to work.
For organizations expanding data access across departments, an enterprise data catalog acts as the single reference point documenting what data exists, who owns it, and how it should be used.
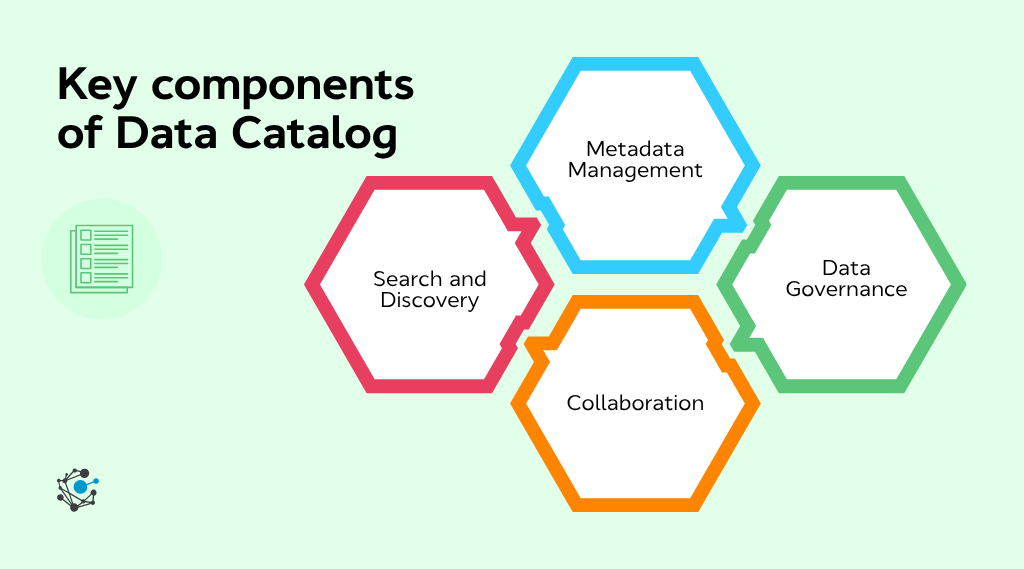
Every catalog is built around four core capabilities:
-
Metadata management: Centralizes descriptive information about each dataset, including its source, structure, format, and relationships with other datasets, so teams can find what they need without chasing down the person who built the pipeline.
-
Search and discovery: Lets users query metadata by keyword, business domain, or data tag to locate the right dataset across the organization in seconds instead of hours.
-
Data governance: Enforces policies, ownership tracking, and role-based access controls that keep sensitive data restricted to authorized users.
-
Collaboration: Provides shared spaces for annotation, tagging, and commenting, so teams can flag quality issues or share context directly on the dataset itself.
For example, when a marketing analyst needs customer churn data, the catalog lets them search by keyword and find the dataset in seconds (search and discovery), check that it comes from the CRM and refreshes weekly (metadata management), confirm they have role-based access to use it (governance), and see a note from the data team flagging a known two-day lag in the source feed (collaboration).
When these capabilities work together, data stops being something only engineers can navigate. Business users across the organization gain self-service access to trusted, well-documented datasets without filing a ticket or waiting on the data team.
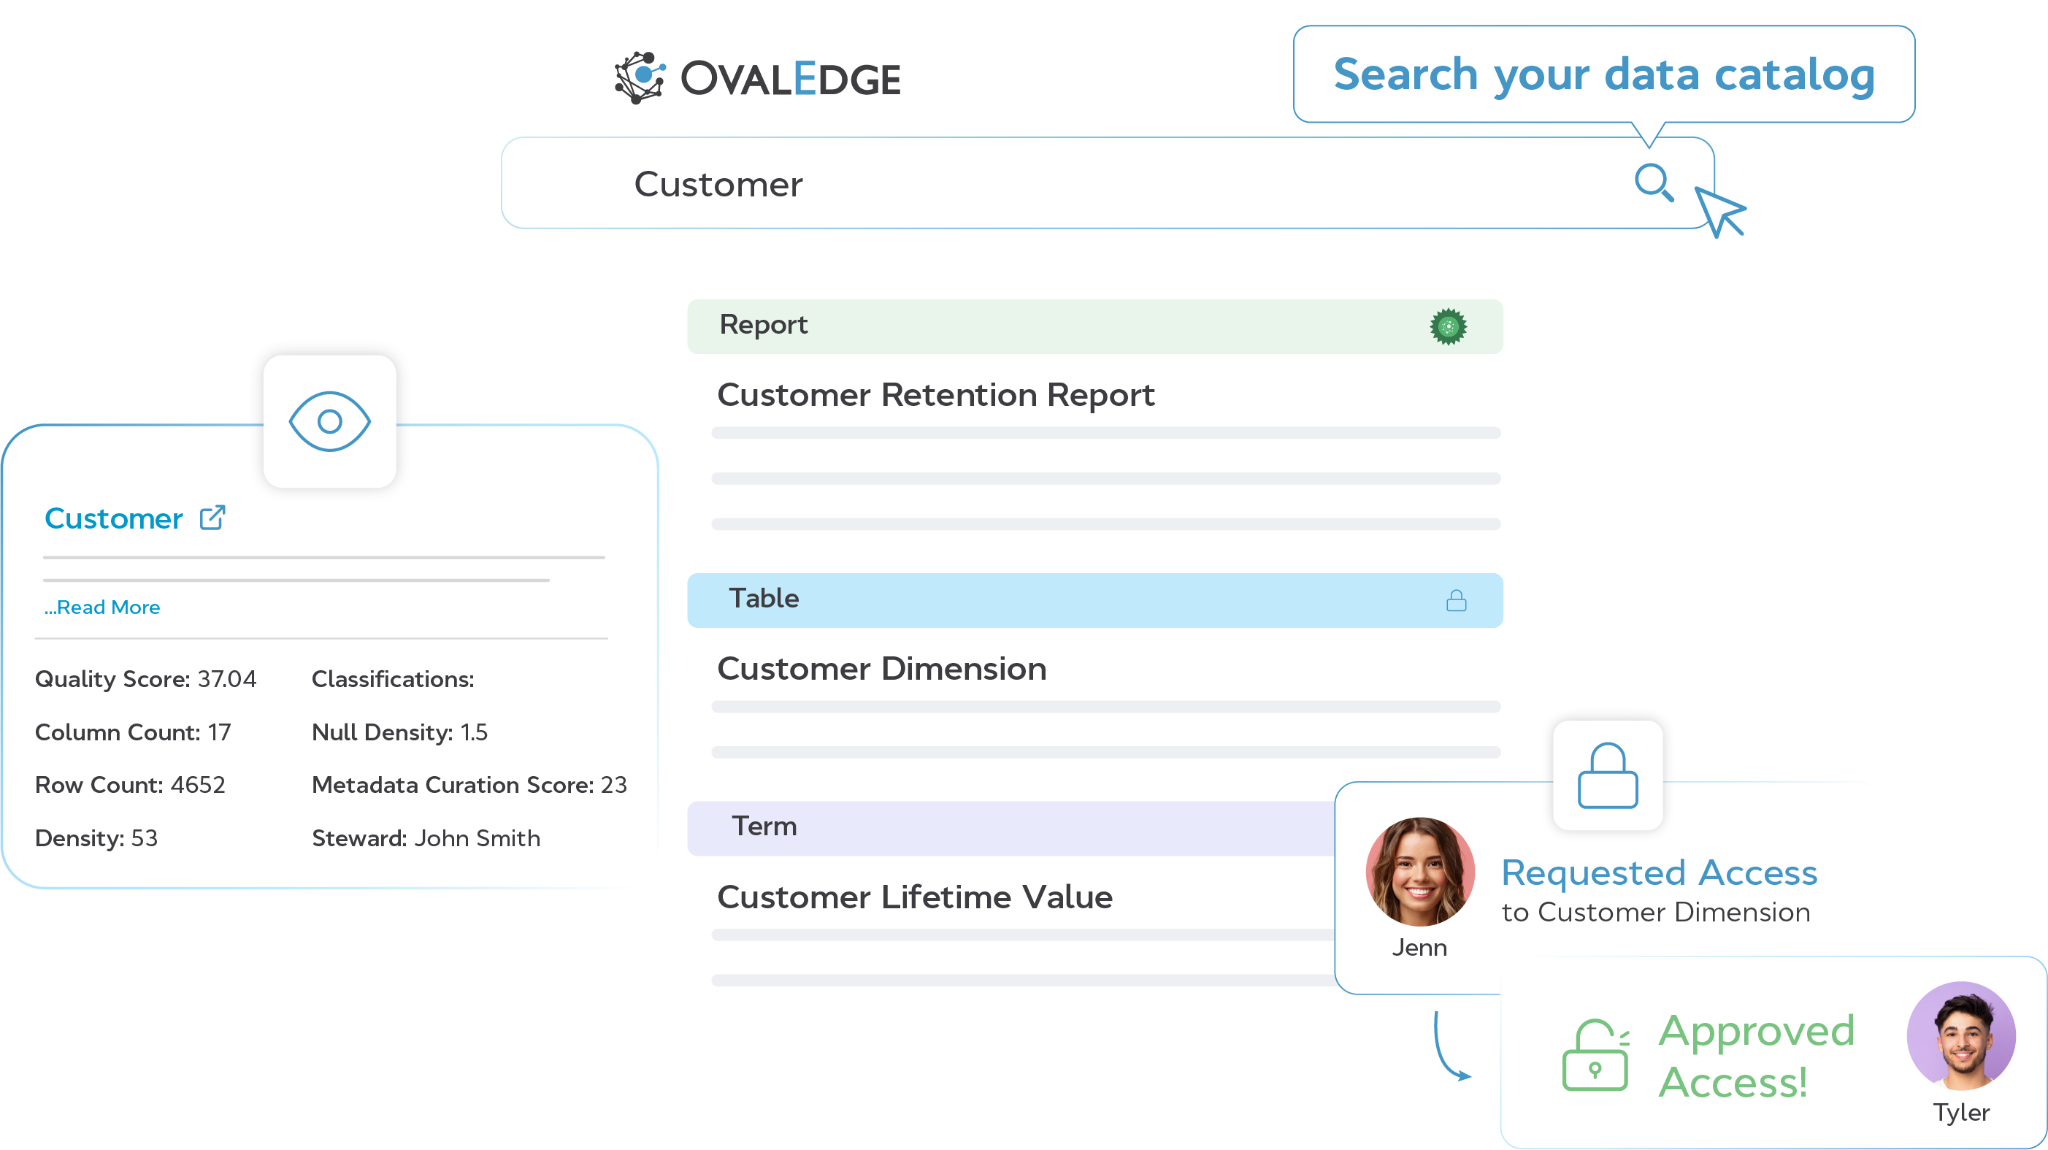
OvalEdge's data catalog unifies metadata from 170+ sources into a single searchable inventory, so teams can find the data they need, understand its context, and govern access without switching between tools.
Also read: Data catalog vs metadata management: where they overlap and where they diverge
How data lineage fits into a data catalog
A data catalog on its own tells you what data exists and where it lives. Lineage adds the missing layer: where that data came from, what happened to it along the way, and what depends on it downstream. Together, they turn a static inventory into a living map that teams can actually trust when making decisions. Most catalog implementations that stall do so because users do not trust the data they find. Lineage is what closes that gap.
1. Provenance and trust.
When a catalog entry says "monthly revenue," lineage shows exactly which source systems feed that number, what transformations were applied, and when the data was last refreshed. Analysts can verify a dataset's reliability in seconds instead of tracking down the engineer who built the pipeline. Full provenance is what turns a catalog from a search tool into a trust layer.
Also read: How Snowflake data lineage connects your warehouse to your catalog
2. Compliance and audit trail.
Regulations like GDPR, HIPAA, and BCBS 239 require organizations to document how data is collected, processed, and stored. Lineage embedded in the catalog creates a continuous audit trail that compliance teams can pull on demand.
For instance, when an auditor asks "where did this customer record originate and who touched it," the answer is already mapped, not buried across three teams and a shared drive. Organizations that build this audit capability into the catalog from day one spend hours on compliance reviews instead of weeks.
3. Impact analysis and data quality.
When a schema change or a source system update breaks a downstream report, lineage pinpoints exactly which tables, columns, and dashboards are affected. Quality issues get traced to their root cause at the transformation step where they were introduced, rather than surfacing only as symptoms in a dashboard that nobody can explain. Teams fix the actual problem instead of patching the output.
4. Self-service trust across teams.
Business users are far more likely to use the catalog independently when they can see a dataset's full history, not just its name and a one-line description. Lineage gives non-technical users the confidence to pull data for their own analysis because they can verify its origin and transformation logic without filing a request to the data team. The result is fewer bottlenecks on data engineering and faster time to insight across the organization.
Data lineage vs data catalog: key differences and similarities
Data lineage tracks where data came from and how it changed. A data catalog organizes metadata so teams can find, understand, and trust it. They solve different problems but work best as a pair. The table below breaks down the key differences and where the two overlap.
|
Aspect |
Data lineage |
Data catalog |
|
Best for |
Impact analysis, root-cause investigation, compliance audits |
Data discovery, governance, self-service access |
|
Primary question answered |
"Where did this come from? How did it change?" |
"What data do we have? Who owns it?" |
|
Primary purpose |
Tracks the flow and transformation of data |
Organizes metadata so data can be found and used |
|
Target users |
Data engineers, compliance officers, and auditors |
Business analysts, data stewards, and governance teams |
|
Core function |
Visual map of data's journey across systems |
Searchable repository of metadata |
|
Key benefit |
Transparency, integrity, and compliance proof |
Discoverability, usability, and governed access |
|
Governance role |
Provides the audit trail that proves rules are followed |
Enforces classifications, ownership, and access policies |
|
Data quality role |
Traces errors to their source |
Surfaces certified, quality-scored assets |
|
Decision-making impact |
Builds trust through traceability |
Builds speed through self-service |
|
Tools and features |
Visual maps, transformation tracking, and audit trails |
Search, tagging, access controls, metadata indexing |
|
OvalEdge approach |
Automated, column-level lineage across catalog, BI, and pipelines |
Unified catalog with embedded lineage, governance, and AI-ready metadata |
On their own, each tool covers half the picture. Combined, they create an integrated governance framework where lineage provides the proof trail and the catalog provides the access layer.
How data lineage and a data catalog operationalize data governance
Lineage and catalogs each have their own job. The governance impact happens when they work as one system, and the place this shows up most clearly is in two areas: change management and audit prep.
1. Change management.
When a data engineer modifies a source schema, deprecates a pipeline, or moves a workload from Oracle to Snowflake, the combined system reveals the full blast radius before the change goes live:
-
The catalog flags which datasets are affected and who owns them.
-
Lineage maps every downstream dashboard, report, and AI model that depends on the data being changed.
- Teams assess impact in minutes instead of discovering breakage from a Slack message at 9 PM.
2. Audit prep.
Compliance teams typically spend weeks before a GDPR or SOX audit pulling together where sensitive data lives and how it was transformed. With catalog and lineage operating as one layer, that provenance trail is already documented. Under BCBS 239, for instance, financial institutions must demonstrate end-to-end data provenance for every risk metric they report to regulators. When both systems are integrated:
-
Auditors get a pre-built lineage view from source to report for any dataset.
-
Classification and sensitivity tags from the catalog show which policies apply.
-
The question shifts from whether you can prove compliance to which view the auditor needs.
Organizations that automate this workflow through governance agents reduce manual audit prep further by continuously validating classification, access policies, and lineage completeness across the catalog.
When to use data lineage vs a data catalog
Reach for data lineage when you need to:
-
Trace where a number on a dashboard came from or why it broke
-
Produce an audit trail for a regulator (GDPR, HIPAA, SOX, AI Act)
-
Map downstream impact before a schema change, system migration, or pipeline deprecation
-
Document training data provenance for an AI model going into production
Reach for a data catalog when you need to:
-
Find a specific dataset by business term instead of file path
-
Identify who owns a dataset, its quality score, and its certification status
-
Enforce role-based access controls at the dataset or column level
-
Standardize business definitions across teams, regions, or business units
You need both at the same time when:
-
A GDPR deletion request requires tracing every system the data passed through (lineage) and confirming every system owner and access policy along the chain (catalog).
-
A schema migration needs a full dependency map of downstream tables and dashboards (lineage) and a way to notify every affected dataset owner before the change goes live (catalog).
-
A new analyst needs to find the right dataset for a project (catalog) and verify that the numbers are accurate and sourced from a trusted pipeline (lineage).
Modern data platforms have stopped treating catalog and lineage as separate purchases. The combined system is where the real value lives.
Which one should you buy first, catalog or lineage?
Most teams do not need both tools on day one. The right starting point depends on where the biggest pain is right now.
Start with a data catalog if:
-
Teams cannot find the data they need without asking a specific engineer or searching through Slack threads.
-
Data ownership is unclear, and multiple teams are duplicating datasets because nobody knows what already exists.
-
Governance and compliance audits require a centralized inventory of data assets that does not exist today.
Also read: Business glossary vs data catalog: which one comes first?
Start with data lineage if:
-
Broken dashboards and reports are a recurring problem, and root cause analysis takes days because nobody can trace the data back to its source.
-
Regulatory audits (GDPR, HIPAA, BCBS 239) require documented proof of how data moves from origin to consumption.
-
A major migration (on-prem to cloud, legacy warehouse to Snowflake or Databricks) is on the roadmap and the team needs to map dependencies before making changes.
Buy a unified platform if:
-
Both pain points above are present, and running two separate tools would mean integrating them yourself.
-
Governance is a priority, and the team needs catalog, lineage, and policy enforcement in a single system.
-
AI model deployment is accelerating, and the organization needs end-to-end provenance from source data through to model output.
Gartner research on context foundations found that organizations with successful AI initiatives invest up to 4x more in data and analytics foundations, and those with the highest maturity achieve up to 65% greater business outcomes.
Organizations in heavily regulated industries like financial services, healthcare, and pharma often land here because compliance requires both capabilities from the start. Platforms like OvalEdge combine catalog, lineage, and governance into one layer, which eliminates the integration overhead and gives teams a single view of their entire data estate from day one.
In short, the practical test for any unified platform is straightforward: can you trace a dashboard back to its production source across five or six systems owned by different teams, in a single query? If the answer requires switching between tools and manually stitching metadata, the integration is cosmetic.
Data lineage and data catalog: the vendor landscape
The market for data lineage and data catalog tools breaks into three categories. Understanding where each vendor fits helps narrow the evaluation.
|
Category |
What it covers |
Examples |
|
Standalone data catalogs |
Metadata management, search and discovery, governance, access controls |
Alation, Collibra |
|
Standalone data lineage |
End-to-end lineage mapping, impact analysis, compliance documentation |
Manta, Octopai |
|
Unified platforms |
Catalog, lineage, governance, business glossary, and policy enforcement in a single system |
OvalEdge, Informatica |
Standalone tools work well when an organization has a clear, narrow need and is willing to integrate multiple vendors. Unified platforms reduce that integration overhead by combining catalog, lineage, and governance under one roof. The trade-off is flexibility vs. time-to-value: standalone tools let teams pick best-of-breed for each function, while unified platforms deliver a connected system out of the box.
OvalEdge falls in the unified category, combining a data catalog with column-level lineage, sensitive data classification, business glossary, and fine-grained access controls across 170+ connectors.
Why data lineage and data catalogs are non-negotiable for AI today
Most serious AI programs are converging on the same foundation: a unified catalog plus lineage, governed end to end. Gartner estimates that 60% of AI projects risk abandonment through 2026 when they lack AI-ready data.
Three shifts are driving this.
1. AI training data needs proof of provenance.
Regulators and internal review boards now ask for evidence that training data was sourced cleanly, transformed correctly, and is free of leakage or bias. Metadata alone cannot answer those questions. Column-level lineage can, because it traces every field back to its origin and documents every transformation applied along the way.
Also read: How column-level data lineage works and why it matters for AI governance
2. Agentic systems break without traceability.
When an AI agent makes a recommendation, approves a transaction, or routes a customer, the team needs to trace that decision back through every dataset and transformation that influenced it. Without lineage, agentic AI becomes a black box nobody can explain to a regulator or a customer.
3. The EU AI Act treats data lineage as a compliance requirement.
Article 10 requires high-risk AI systems to document where training data came from, how it was prepared, and what biases it contains. Catalogs without lineage will not satisfy that requirement. Similar frameworks are being adopted in the UK, the US, and APAC.
The platforms handling this well treat catalog and lineage as one governance layer. The Agentic Analytics whitepaper covers how this works in practice and where it is headed next.
Data lineage and data catalog: a single governance system
Data lineage and data catalogs are two halves of one governance system. The catalog identifies what data exists and who owns it. Lineage shows where that data came from and how it changed. Run them separately, and governance stays a written policy. Run them together, and it becomes something the organization can enforce, audit, and prove.
The organizations getting this right run both on a single platform where every dataset is inventoried, every transformation is traced, and every access policy is enforced from one place.
OvalEdge connects catalog, column-level lineage, governance, and access controls through the Enterprise Context Graph, giving teams one system to discover, trace, and govern their entire data estate.
Book a 30-minute demo, and we will run a lineage trace on your own data