Retrieval-Augmented Generation (RAG) has become the default architecture for grounding enterprise AI in internal data. Data governance for RAG systems determines whether that grounding produces reliable answers, because RAG retrieves whatever exists in the knowledge base, including conflicting definitions, stale documents, and restricted content.
Deloitte's 2025 Chief Data Officer Survey found that 51% of CDOs ranked data governance as their top priority for the year ahead, reflecting a growing recognition that scaling AI on ungoverned data creates compliance, quality, and trust risks that compound with every new deployment.
The same governance foundations that support analytics and compliance (business glossary, lineage, quality rules, access policies) apply directly to RAG, ensuring AI-generated answers draw from trusted, governed sources.
The guide covers the core components of a RAG governance framework, how governance reduces hallucinations, security and compliance requirements, and practical best practices for extending existing governance to the retrieval layer.
What is data governance for RAG systems?
Data governance for RAG systems is the set of policies, metadata controls, quality standards, and access rules that ensure Retrieval-Augmented Generation (RAG) pulls from trusted, well-defined, and permission-appropriate enterprise data.
While RAG has become the default architecture for grounding Large Language Models (LLMs) in internal knowledge, governance determines whether that grounding produces reliable answers or amplifies the inconsistencies already present in the knowledge base.
How RAG works (and where governance enters)
Enterprise RAG operates in three stages. First, the system chunks, embeds, and indexes internal content (documents, databases, glossaries, reports, and knowledge articles) in a vector database or hybrid search system. Second, when a user submits a query, the retriever identifies and surfaces the most relevant content chunks. Third, the LLM generates an answer grounded in that retrieved context.
Governance decisions exist at every stage. During indexing, governance determines what content qualifies for inclusion. During retrieval, governance controls which content a specific user can access and which business definition is authoritative. During generation, governance supports auditability by ensuring the output traces back to its source documents.
How RAG governance differs from traditional data governance
Traditional data governance applies policies, roles, and controls to structured data assets at rest. RAG governance extends those controls to unstructured content, chunk-level quality assessments, retrieval-time access enforcement, and output traceability.
A data warehouse stores governed tables that analysts query through defined interfaces. A RAG knowledge base stores document chunks that an LLM consumes programmatically, often without a human reviewing which chunks entered the context window.
Governance for this environment requires metadata, lineage, quality signals, and access controls that travel with the content and remain enforceable at the moment of retrieval, because the knowledge base is no longer a passive repository. It is an active input to AI-generated decisions.
How governance requirements shift across RAG architectures
Enterprise RAG deployments typically follow one of two retrieval architectures, and each carries distinct governance requirements.
Vector-based RAG converts content into numerical embeddings and retrieves semantically similar chunks from a vector database. Governance for this architecture focuses on embedding quality standards, chunk-level metadata management, efficient indexing, and data retention policies for the vector store. Because vector search operates on semantic similarity, the system can surface content that is linguistically close to a query without understanding the business context behind it, making governed metadata and glossary integration especially important.
Graph-based RAG retrieves content through knowledge graphs that represent structured relationships between entities, concepts, and data points. Governance for this architecture requires ontology management, taxonomy validation, relationship integrity checks, and versioning controls for graph nodes and edges.
The overlap between the two architectures is substantial. Data quality, access controls, lineage tracking, compliance enforcement, and metadata management apply regardless of which retrieval method the system uses. The five framework components covered in this guide address those shared governance requirements.
Organizations running hybrid architectures, combining vector search with graph traversal, need governance controls that span both retrieval paths and maintain consistency across them.
Why does RAG without governance fail?
RAG retrieves from whatever exists in the knowledge base. It does not verify, reconcile, or validate. When the underlying content is inconsistent, outdated, or ungoverned, RAG scales those problems into every AI-generated answer, confident and unable to distinguish a certified source from a stale spreadsheet.
Gartner's 2025 research on the viability of agentic AI predicts that more than 40% of agentic AI projects will be canceled by the end of 2027 due to escalating costs, unclear business value, or inadequate risk controls. A significant share of those failures will trace back to AI systems built on top of ungoverned knowledge.
The retrieval trust problem
Better retrieval does not produce better answers when the underlying data is inconsistent. Every governance gap in the knowledge base creates a specific failure mode at the retrieval layer:
-
Conflicting definitions across systems mean RAG retrieves competing answers to the same question, with no signal to resolve the conflict
-
Missing lineage means RAG cannot explain where an answer came from or how the source data was transformed
-
Disconnected quality rules mean RAG cannot assess whether retrieved content is reliable enough to ground an AI answer
-
Unattached policies mean RAG cannot enforce what content should be restricted from specific users or use cases
Well-tuned embeddings, optimized chunking, and hybrid search do not compensate for a knowledge base where "customer" means five different things across CRM, finance, and support, with no governance signal telling the retriever which definition applies.
What ungoverned RAG looks like in practice
Ungoverned RAG failures rarely surface as errors. The system returns a confident, well-formatted answer, and the user has no reason to question it until the number contradicts a trusted source downstream.
For example: A finance analyst asks the RAG system, "What was customer revenue last quarter?" The knowledge base contains three revenue tables with different aggregation rules, two conflicting definitions of "customer," and no certification status on any source. The system generates a confident number without attribution.
The analyst uses that number in a board presentation. The CFO flags it does not match the audited figure. Investigation reveals the RAG system blended data from an unapproved staging table with a production report, and no governance signal existed to distinguish the authoritative source from the informal alternative.
Core components of a RAG governance framework
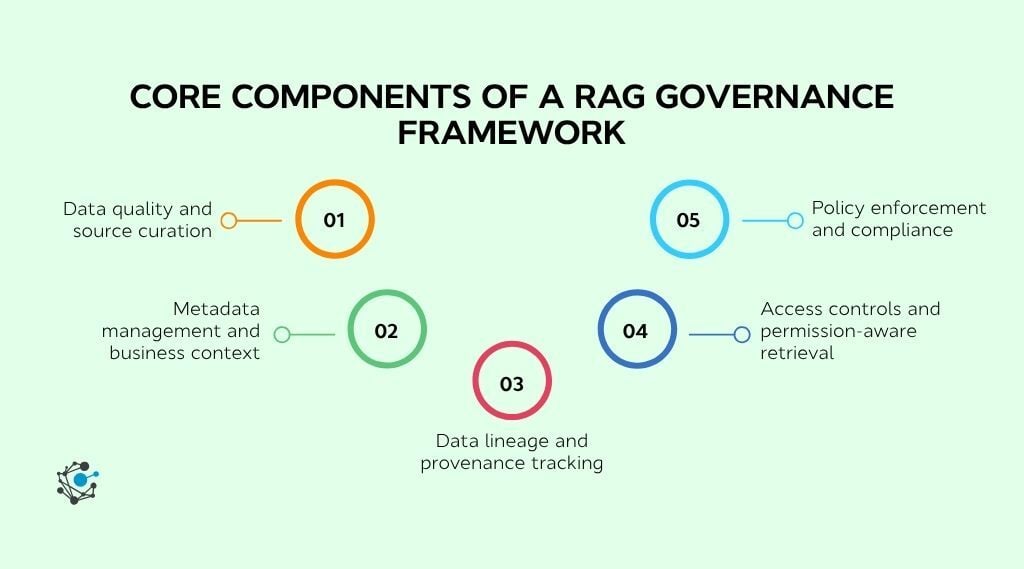
A RAG governance framework covers five capabilities: data quality, metadata, lineage, access controls, and policy enforcement. Each addresses a specific failure mode in the retrieval pipeline.
1. Data quality and source curation
The accuracy, freshness, and completeness of the knowledge base set the ceiling for RAG output quality. Source curation means only trusted, reviewed content enters the retrieval index. Organizations should establish review cycles and use quality scoring as a retrieval filter, deprioritizing or excluding low-confidence content.
Enterprise-grade data quality management extends naturally to RAG when quality scores, freshness indicators, and completeness checks travel with each indexed document. The retriever can then rank sources accordingly, ensuring a certified quarterly report outranks an undated internal memo on the same topic.
2. Metadata management and business context
Metadata enriches retrieved content with business meaning. Without it, the retriever cannot distinguish between assets that share the same name but carry different definitions across departments. Business glossary terms, ownership labels, sensitivity tags, and certification status should travel with indexed content so the retrieval layer can select the most contextually appropriate result.
Metadata-enriched retrieval produces sharper answers because the system can match a query about "net revenue" to the finance-approved definition rather than surfacing every document that mentions the phrase.
3. Data lineage and provenance tracking
Lineage answers two critical questions for RAG: where did this data come from, and how was it transformed before it entered the index? In a retrieval context, lineage enables source attribution, which means every AI-generated answer can trace back to the document, table, or report that grounded it.
Provenance tracking supports impact analysis. When a source document changes, lineage identifies which downstream RAG outputs may be affected, allowing teams to flag or regenerate answers that relied on outdated content.
OvalEdge expert insight: Organizations that have already invested in metadata, lineage, and business definitions hold a significant advantage when deploying RAG. The governance foundation for AI-ready retrieval is often already partially built.
4. Access controls and permission-aware retrieval
Access control in RAG must happen before retrieval. If the source system restricts a document, the RAG retriever must also exclude it for unauthorized users. Permission-aware retrieval filters content based on the requesting user's role, clearance, or organizational context.
Without pre-retrieval enforcement, RAG becomes a potential pathway to restricted data. Propagating source-system permissions to the retrieval index closes this gap.
OvalEdge expert insight: OvalEdge's Enterprise Context Graph continuously links catalog, glossary, lineage, quality scores, and access policies into a single connected graph. Organizations that have already built governance foundations for analytics can extend that same graph to the retrieval layer rather than rebuilding for AI.
5. Policy enforcement and compliance
Governance policies covering retention schedules, classification requirements, and usage restrictions must extend to the RAG knowledge base. Regulatory frameworks such as GDPR, HIPAA, and the EU AI Act impose specific obligations regarding what data may appear in AI-generated outputs and how long it may be retained across systems, including vector databases where content has been embedded and indexed.
Policy enforcement at the retrieval layer prevents regulated content from surfacing in non-compliant contexts. Lifecycle management carries three requirements that most early deployments miss:
-
When a source document is updated or deleted, the corresponding embeddings and cached chunks must also be updated or removed
-
Under GDPR, erasure requests extend to every system holding personal data, including the retrieval index
-
Query logs, response caches, and pipeline outputs each require defined retention periods and access controls
Compliance logging, where every retrieval action produces an auditable record, closes the accountability loop that regulators increasingly demand.
How governance reduces hallucinations in enterprise RAG
Hallucinations in RAG systems most often trace back to retrieval problems rather than model problems. The LLM generates a plausible-sounding answer because the retriever surfaced conflicting, outdated, or low-quality content. Governance addresses this root cause by ensuring only trusted, certified, and contextually appropriate content reaches the model's context window.
Source certification and retrieval filtering work together to address this. Only documents that meet defined criteria (assigned ownership, verified quality score, confirmed freshness) should qualify for indexing, and trust signals attached to each document give the retriever the information it needs to prioritize authoritative sources. At retrieval time, three governance signals shape what the LLM receives:
-
Lineage metadata enables the retriever to prefer authoritative primary sources over derived or secondary content
-
Quality signals like completeness, accuracy, and recency filter out low-confidence content before it enters the context window
-
Ownership metadata helps route queries to the right domain when confidence is low
Platforms with column-level data lineage can trace exactly how a certified dataset was built, transformed, and approved.
OvalEdge expert insight: OvalEdge exposes governance metadata to RAG pipelines through its MCP Server and open context APIs, so quality scores, lineage, and certification status become retrieval inputs that shape what the model receives, not documentation sitting in a catalog no one checks.
Security and compliance requirements for enterprise RAG
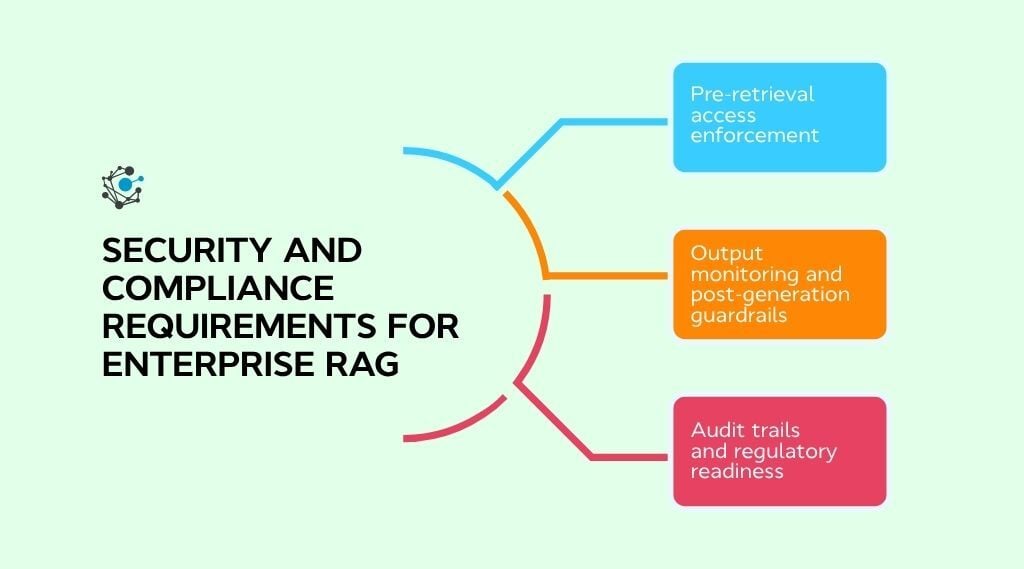
Enterprise RAG creates a new attack surface. Documents that were access-controlled in their source systems can become exposed through retrieval if permissions are not enforced at the RAG layer. Security and compliance demand that organizations treat the retrieval pipeline with the same rigor they apply to direct data access.
1. Pre-retrieval access enforcement
Source-system permissions must propagate to the RAG index. Role-Based Access Control (RBAC) and Attribute-Based Access Control (ABAC) should operate at the retrieval layer, filtering content before it enters the model's context window.
Post-generation filtering is insufficient because the model has already ingested sensitive data during generation. Governed data access controls that enforce permissions before retrieval close this gap by ensuring the LLM never processes content the requesting user is not authorized to see.
Zero Trust principles apply directly to RAG: the system should never trust that retrieved content is appropriate without verifying the user's authorization at the moment of the query.
2. Output monitoring and post-generation guardrails
Pre-retrieval controls reduce risk at the source, but they do not cover every failure mode. Output monitoring adds a second layer by scanning generated responses before they reach the user. Automated classifiers can flag responses that contain:
-
Personal identifiers or sensitive content categories that passed retrieval filters
-
Statements that contradict the retrieved source documents, indicating a hallucination
-
Content from restricted domains appearing in contexts where it should not surface
For high-risk use cases involving financial, medical, or legal outputs, human review before delivery provides a governance layer that automated monitoring cannot fully replace.
3. Audit trails and regulatory readiness
Every retrieval action should produce an audit log capturing the query, retrieved content, generated output, and requesting user. Regulatory frameworks increasingly require explainability for AI-generated outputs, and AI governance and data governance both contribute to the audit scope.
The EU AI Act classifies certain AI applications as high-risk and imposes transparency and documentation requirements. GDPR's data subject rights extend to automated decision-making. HIPAA governs the use of protected health information in any system, including AI outputs. Each framework requires organizations to trace an AI answer back to its source documents, retrieval logic, and access authorization.
The EU AI Act also requires meaningful human oversight for high-risk AI applications, and GDPR Article 22 restricts fully automated decision-making that produces legal or similarly significant effects on individuals. Organizations deploying RAG for use cases involving eligibility decisions, medical guidance, or financial recommendations should build human review workflows into the response pipeline before production deployment.
OvalEdge expert insight: OvalEdge's Source Code Intelligence parses production SQL, ETL, BI models, and stored procedures to produce exact, code-level lineage rather than inferences from query logs. When an auditor asks where a RAG-generated answer came from, the lineage traces back to the actual logic, not an approximation.
Why governed metadata is the missing RAG foundation?
Most RAG governance conversations focus on retrieval mechanics: vector search optimization, chunking strategies, re-ranking algorithms, and prompt engineering. The more consequential question is whether the enterprise knowledge being indexed is defined, trusted, owned, and governed.
According to McKinsey's The State of AI in 2025 report, nearly 80% of organizations use AI in at least one business function, yet only about one-third report scaling AI across the enterprise. A significant contributor to that gap is the absence of governed, machine-readable metadata that AI systems, including RAG pipelines, need to operate reliably at scale.
The business glossary as a disambiguation layer
When a RAG system retrieves content about "customer revenue," the business glossary determines which definition of "customer" and which calculation of "revenue" is authoritative. Organizations have maintained glossaries for years. The shift is making them machine-readable and connected to the retrieval index so AI systems consume them the same way a human analyst consults a glossary before running a report.
The Enterprise Context Graph: from documentation to retrieval infrastructure
Glossary definitions, lineage, quality signals, and ownership metadata each solve part of the retrieval trust problem. Individually, they sit in separate tools or documentation. Connected into a single graph, they become operational infrastructure that a RAG pipeline can query at retrieval time.
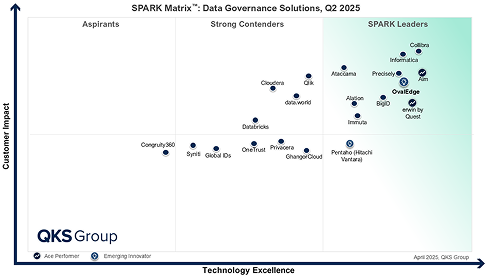
This is what OvalEdge's Enterprise Context Graph (ECG) does. The ECG continuously links ontology, glossary terms, column-level lineage, catalog metadata, quality scores, and access policies into one evolving graph, so every retrieval decision draws from the same trusted context.
Three capabilities make the ECG directly consumable by AI:
-
Source Code Intelligence reads production SQL, ETL pipelines, BI models, and stored procedures to extract exact business logic, formulas, and lineage paths from the actual code rather than inferring them from query logs. The result is ground-truth definitions and transformations that feed directly into the graph.
-
The MCP Server and open context APIs expose the ECG to Claude, ChatGPT, custom agents, and RAG pipelines. AI systems can retrieve trusted definitions, lineage, quality scores, and access policies at runtime without custom integration work.
-
OvalEdge Agents continuously curate the graph by discovering business terms, detecting naming conflicts, classifying sensitive data, assigning ownership, and recommending quality rules, with humans reviewing and approving every action.
The shift from governance as documentation to governance as operational context is what makes enterprise RAG reliable at scale. When definitions, lineage, and trust signals are connected in a single graph and exposed through standard protocols, they stop being artifacts a steward maintains and become inputs that shape every AI-generated answer.
What are the best practices for governing enterprise RAG systems?
The following practices extend existing governance disciplines to the RAG retrieval pipeline. Each one maps to a failure mode covered earlier in this guide.
-
Certify sources before indexing: Only content that passes governance review (ownership assigned, quality scored, freshness verified) should enter the RAG corpus. Uncertified content introduces inconsistency, staleness, and accountability gaps.
-
Attach metadata to every indexed document: Classification tags, glossary terms, ownership records, sensitivity labels, and certification status should travel with each content chunk for more precise retrieval.
-
Enforce access controls at the retrieval layer: Source-system permissions must propagate to the retrieval index. Post-generation filtering does not prevent the model from processing restricted content during generation.
-
Integrate the business glossary into retrieval logic: When a query contains an ambiguous business term, the retriever should resolve it against the governed definition rather than retrieving every document that mentions the term.
-
Use lineage for source attribution: Every AI-generated answer should trace back to a source document with lineage attached. Attribution builds user trust and satisfies auditability requirements under frameworks like the EU AI Act.
At OvalEdge, we believe enterprises should govern once and reuse trusted context across analytics, compliance, and AI retrieval. A unified governance foundation eliminates duplicate effort and ensures the same certified metadata supports every consumer, whether human or machine.
Conclusion
RAG gives enterprise AI access to internal knowledge. Governance determines whether that knowledge is accurate, current, authorized, and worth retrieving. Organizations that treat retrieval and governance as separate initiatives will keep building pipelines that scale ungoverned data into confident, unreliable AI answers.
The practical path forward starts with an audit of the governance foundations already in place. Catalog, glossary, lineage, quality rules, access policies, and compliance controls that organizations built for analytics and reporting apply directly to the retrieval layer. Extending them to the RAG pipeline is faster and more reliable than building a parallel AI governance program from scratch.
OvalEdge helps organizations extend their governance foundation to the retrieval layer by connecting metadata, lineage, quality signals, and access controls in a unified platform that AI systems, including RAG pipelines, can consume at runtime.
Ready to govern the data your AI retrieves?
Schedule a data governance demo to see how OvalEdge makes your existing governance operational for enterprise RAG.